Which distance measure should you use for multivariate time series?
Published:
TL;DR If you need a distance measure for multivariate time series and have no time to experiment, start with the channel-dependent Shape-based Distance (SBD-D): in our SIGMOD 2025 study it gave the best accuracy for its runtime, and it has no parameters to tune. If speed is everything, use Lorentzian distance instead of Euclidean; if accuracy is everything and you can afford days of compute, use a tuned channel-independent elastic measure like MSM-I. And do not assume z-score normalization helps: on the 30 datasets we tested, not normalizing at all ranked first.
Why this is a harder question than it looks
For a univariate time series, a distance measure only has to decide how to deal with time. Two recordings of the same event can be shifted, stretched, or noisy, and the measure either corrects for those distortions or it does not. Decades of work have gone into this, and we have a good idea of what works.
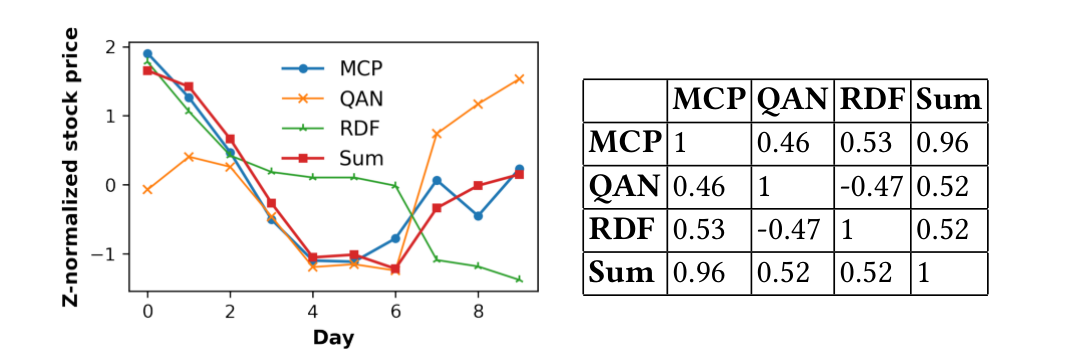
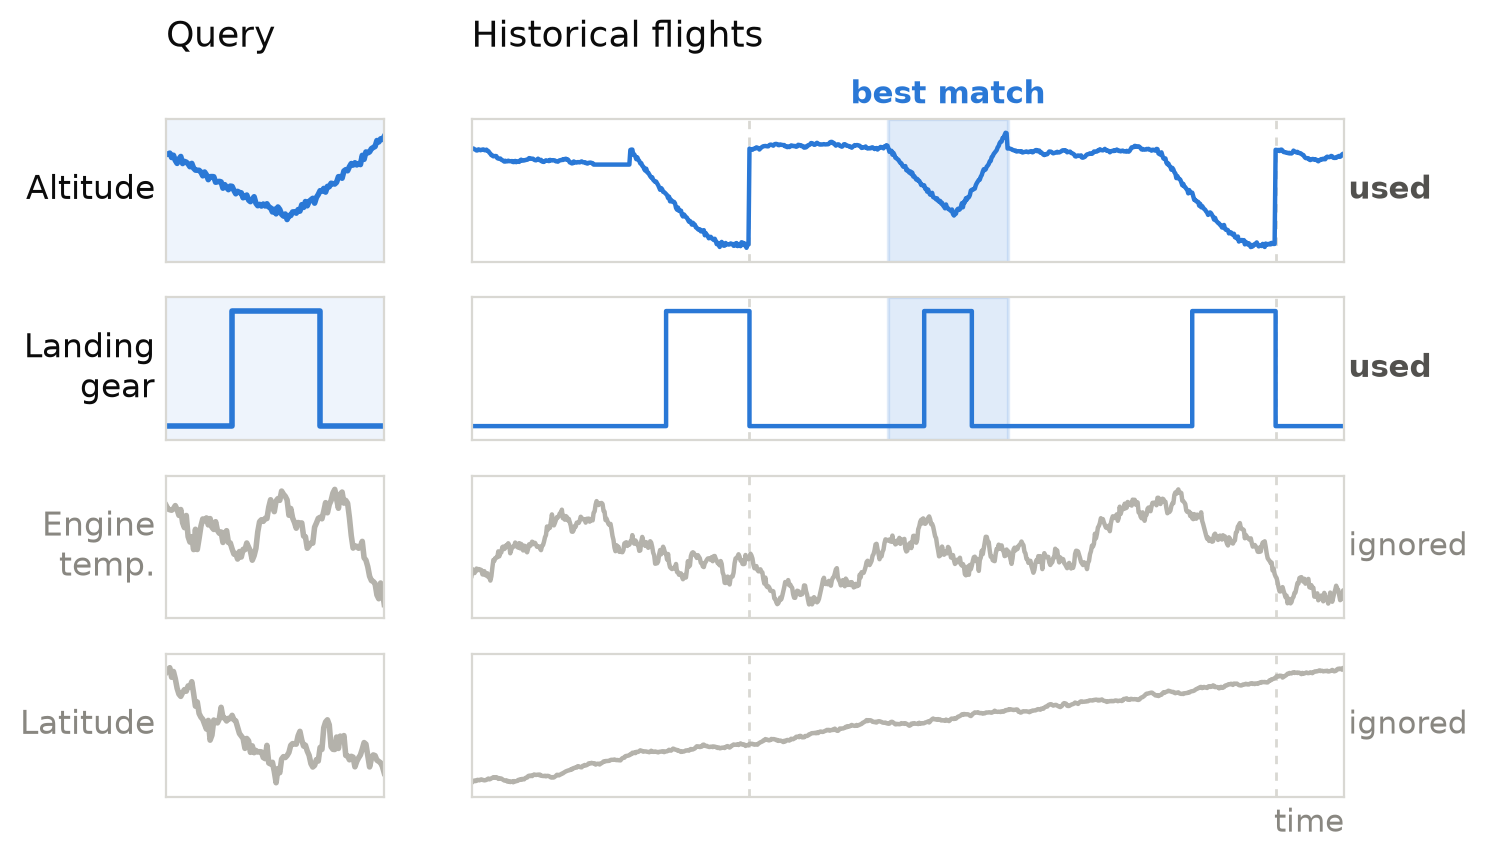
Multivariate time series add a second question: how do you deal with the channels? You can treat every channel as its own univariate series, compute a distance per channel, and add them up. We call that the channel-independent model. Or you can treat the whole matrix as one object, so that a shift or a warping is shared by all channels. That is the channel-dependent model. For DTW these are the well-known DTW-I and DTW-D variants, and the same split exists for almost every other measure, and for normalization too: do you z-score each channel on its own, or with statistics over the whole series?
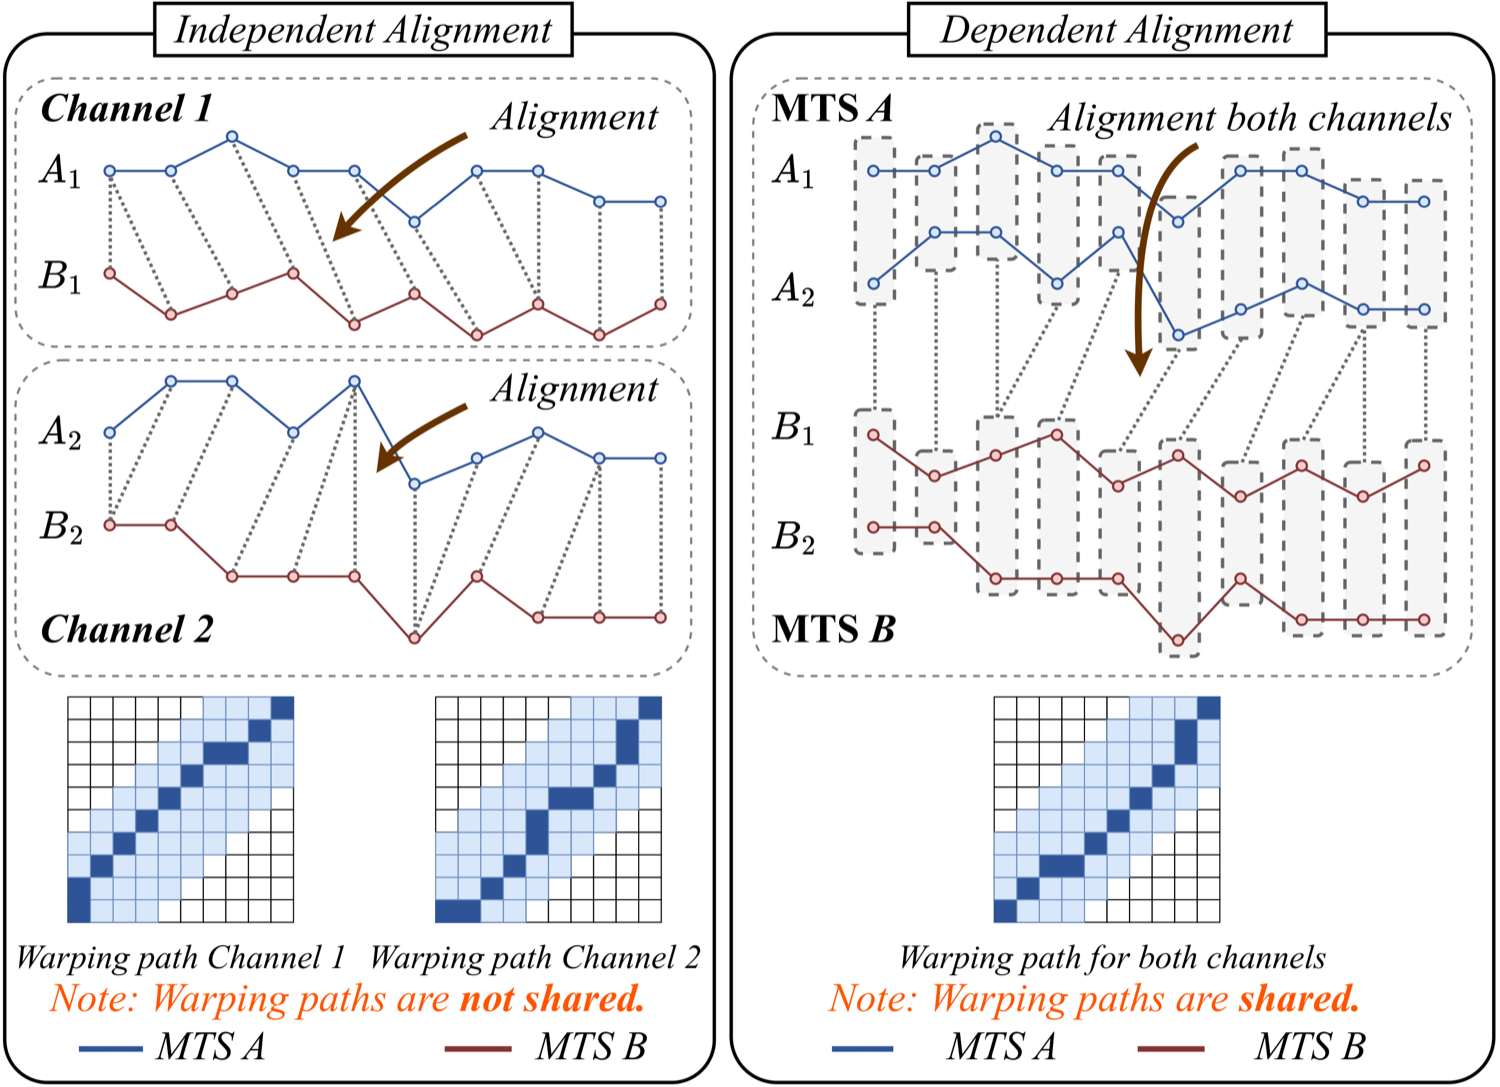
Almost all earlier work on multivariate distances only ever tried per-channel z-score, and only compared lock-step and elastic measures. That left a lot of the design space untested, which is what motivated the study.
The families of measures, in plain words
The survey we wrote with John Paparrizos’ group groups more than 100 measures into seven categories. The SIGMOD study uses the same categories, plus ensembles as an eighth.
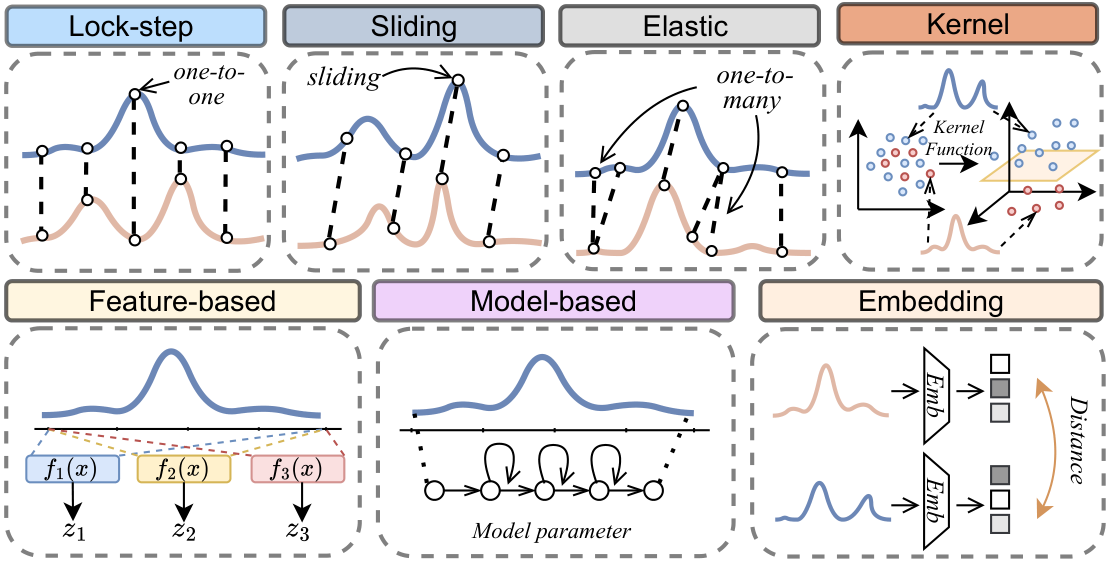
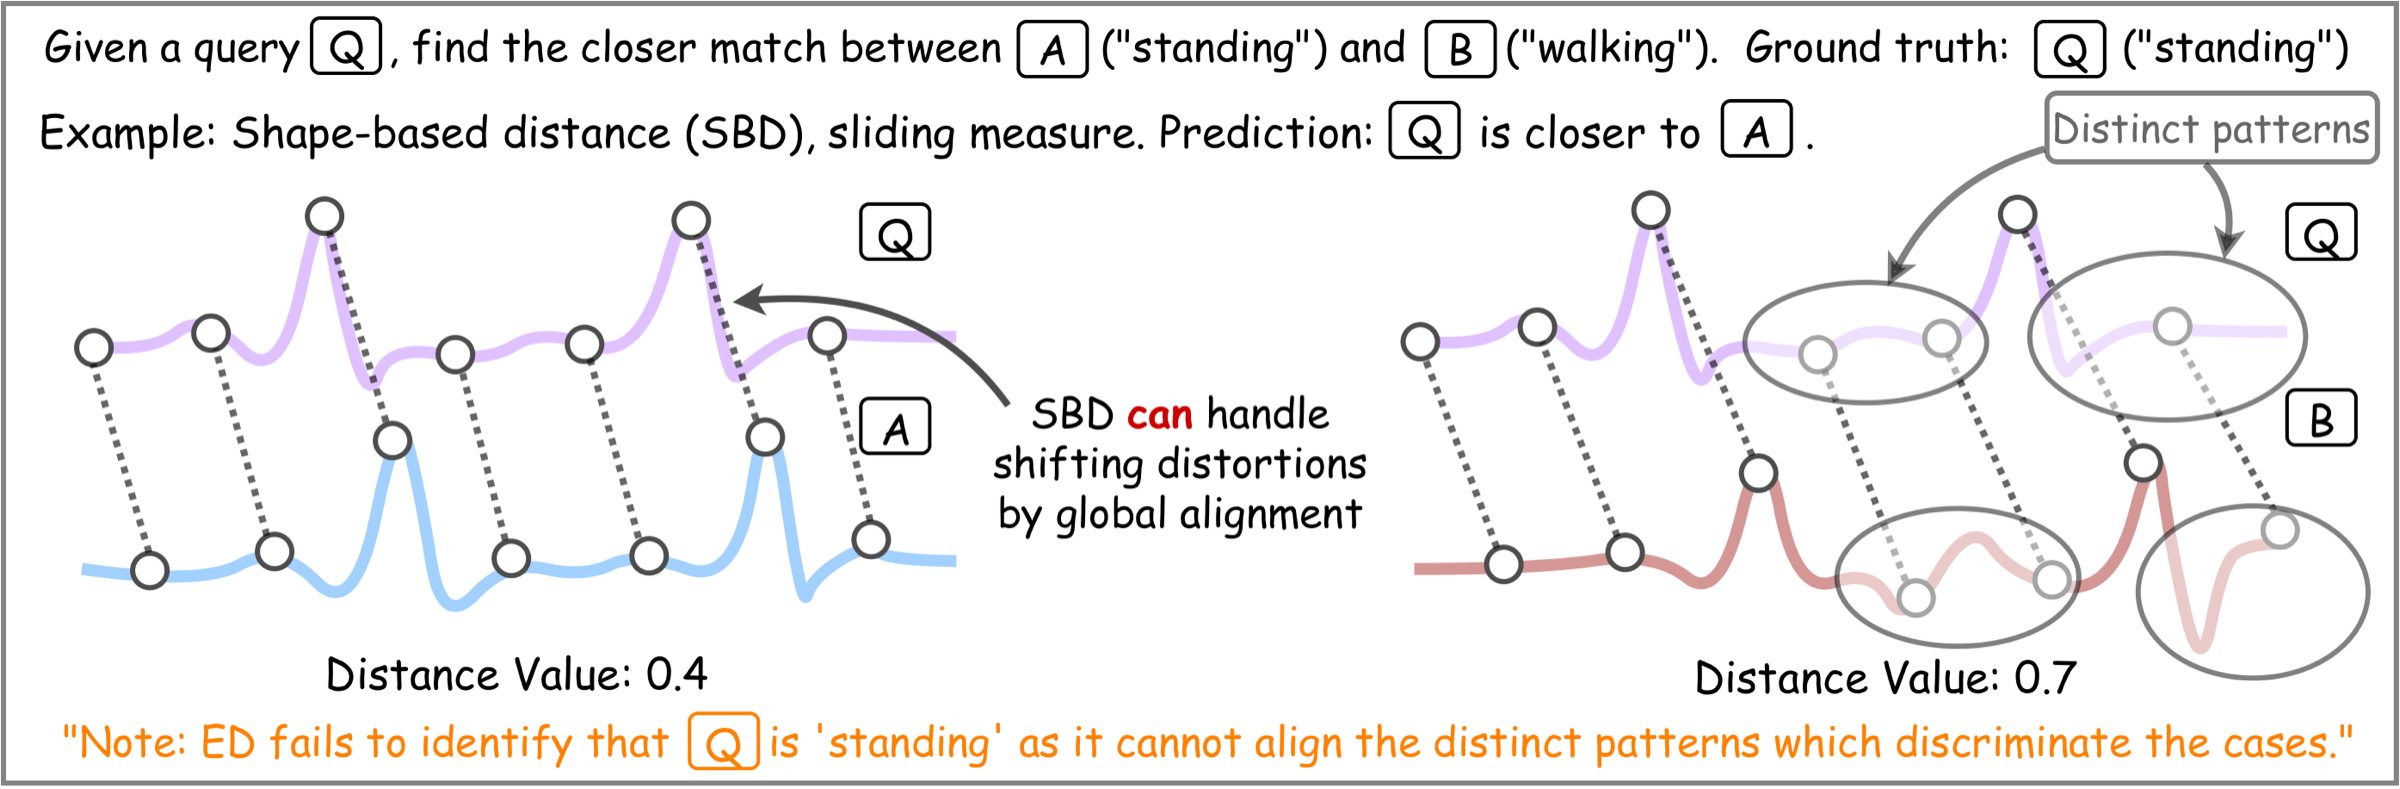
- Lock-step measures compare value i of one series with value i of the other and add up the differences. Euclidean is the obvious example; Lorentzian and L1 are others. Fast, but blind to misalignment in time.
- Sliding measures try every global shift between the two series and keep the best one. SBD, the distance behind k-Shape clustering, is the standard example.
- Elastic measures allow one-to-many mappings between time points, so they absorb local stretching and compression. DTW is the famous one; newer members include MSM, TWE, ERP, and LCSS.
- Kernel measures implicitly map series to a higher-dimensional space through a kernel function, such as GAK or SINK.
- Feature-based measures replace a series with a vector of statistics (mean, entropy, slope, and so on) and compare those. Catch22 and TSFresh are the common feature sets.
- Model-based measures fit a probabilistic model, such as a Gaussian or an HMM, to each series and compare the models, for example with KL divergence.
- Embedding measures learn a new representation and compute a distance there. Deep learning methods like TS2Vec live here, alongside GRAIL and PCA-based measures.
What the study did
We evaluated 30 standalone measures across these 8 categories, each in channel-independent and channel-dependent form where that makes sense (46 variants in total), combined with 13 normalization methods plus the option of not normalizing. Accuracy was measured with a 1-NN classifier on all 30 datasets of the UEA archive, both with supervised parameter tuning (leave-one-out cross-validation) and with a single default setting, and the main comparisons were repeated on clustering (UEA) and anomaly detection (the TSB-AD-M archive, 200 series). Differences were checked with Wilcoxon and Friedman-Nemenyi tests rather than eyeballed. The code is on GitHub as MTSDistEval.
A practical decision guide
The table below is my reading of Table 11 and Section 6 of the paper.
| If your situation is… | Start with | Why |
|---|---|---|
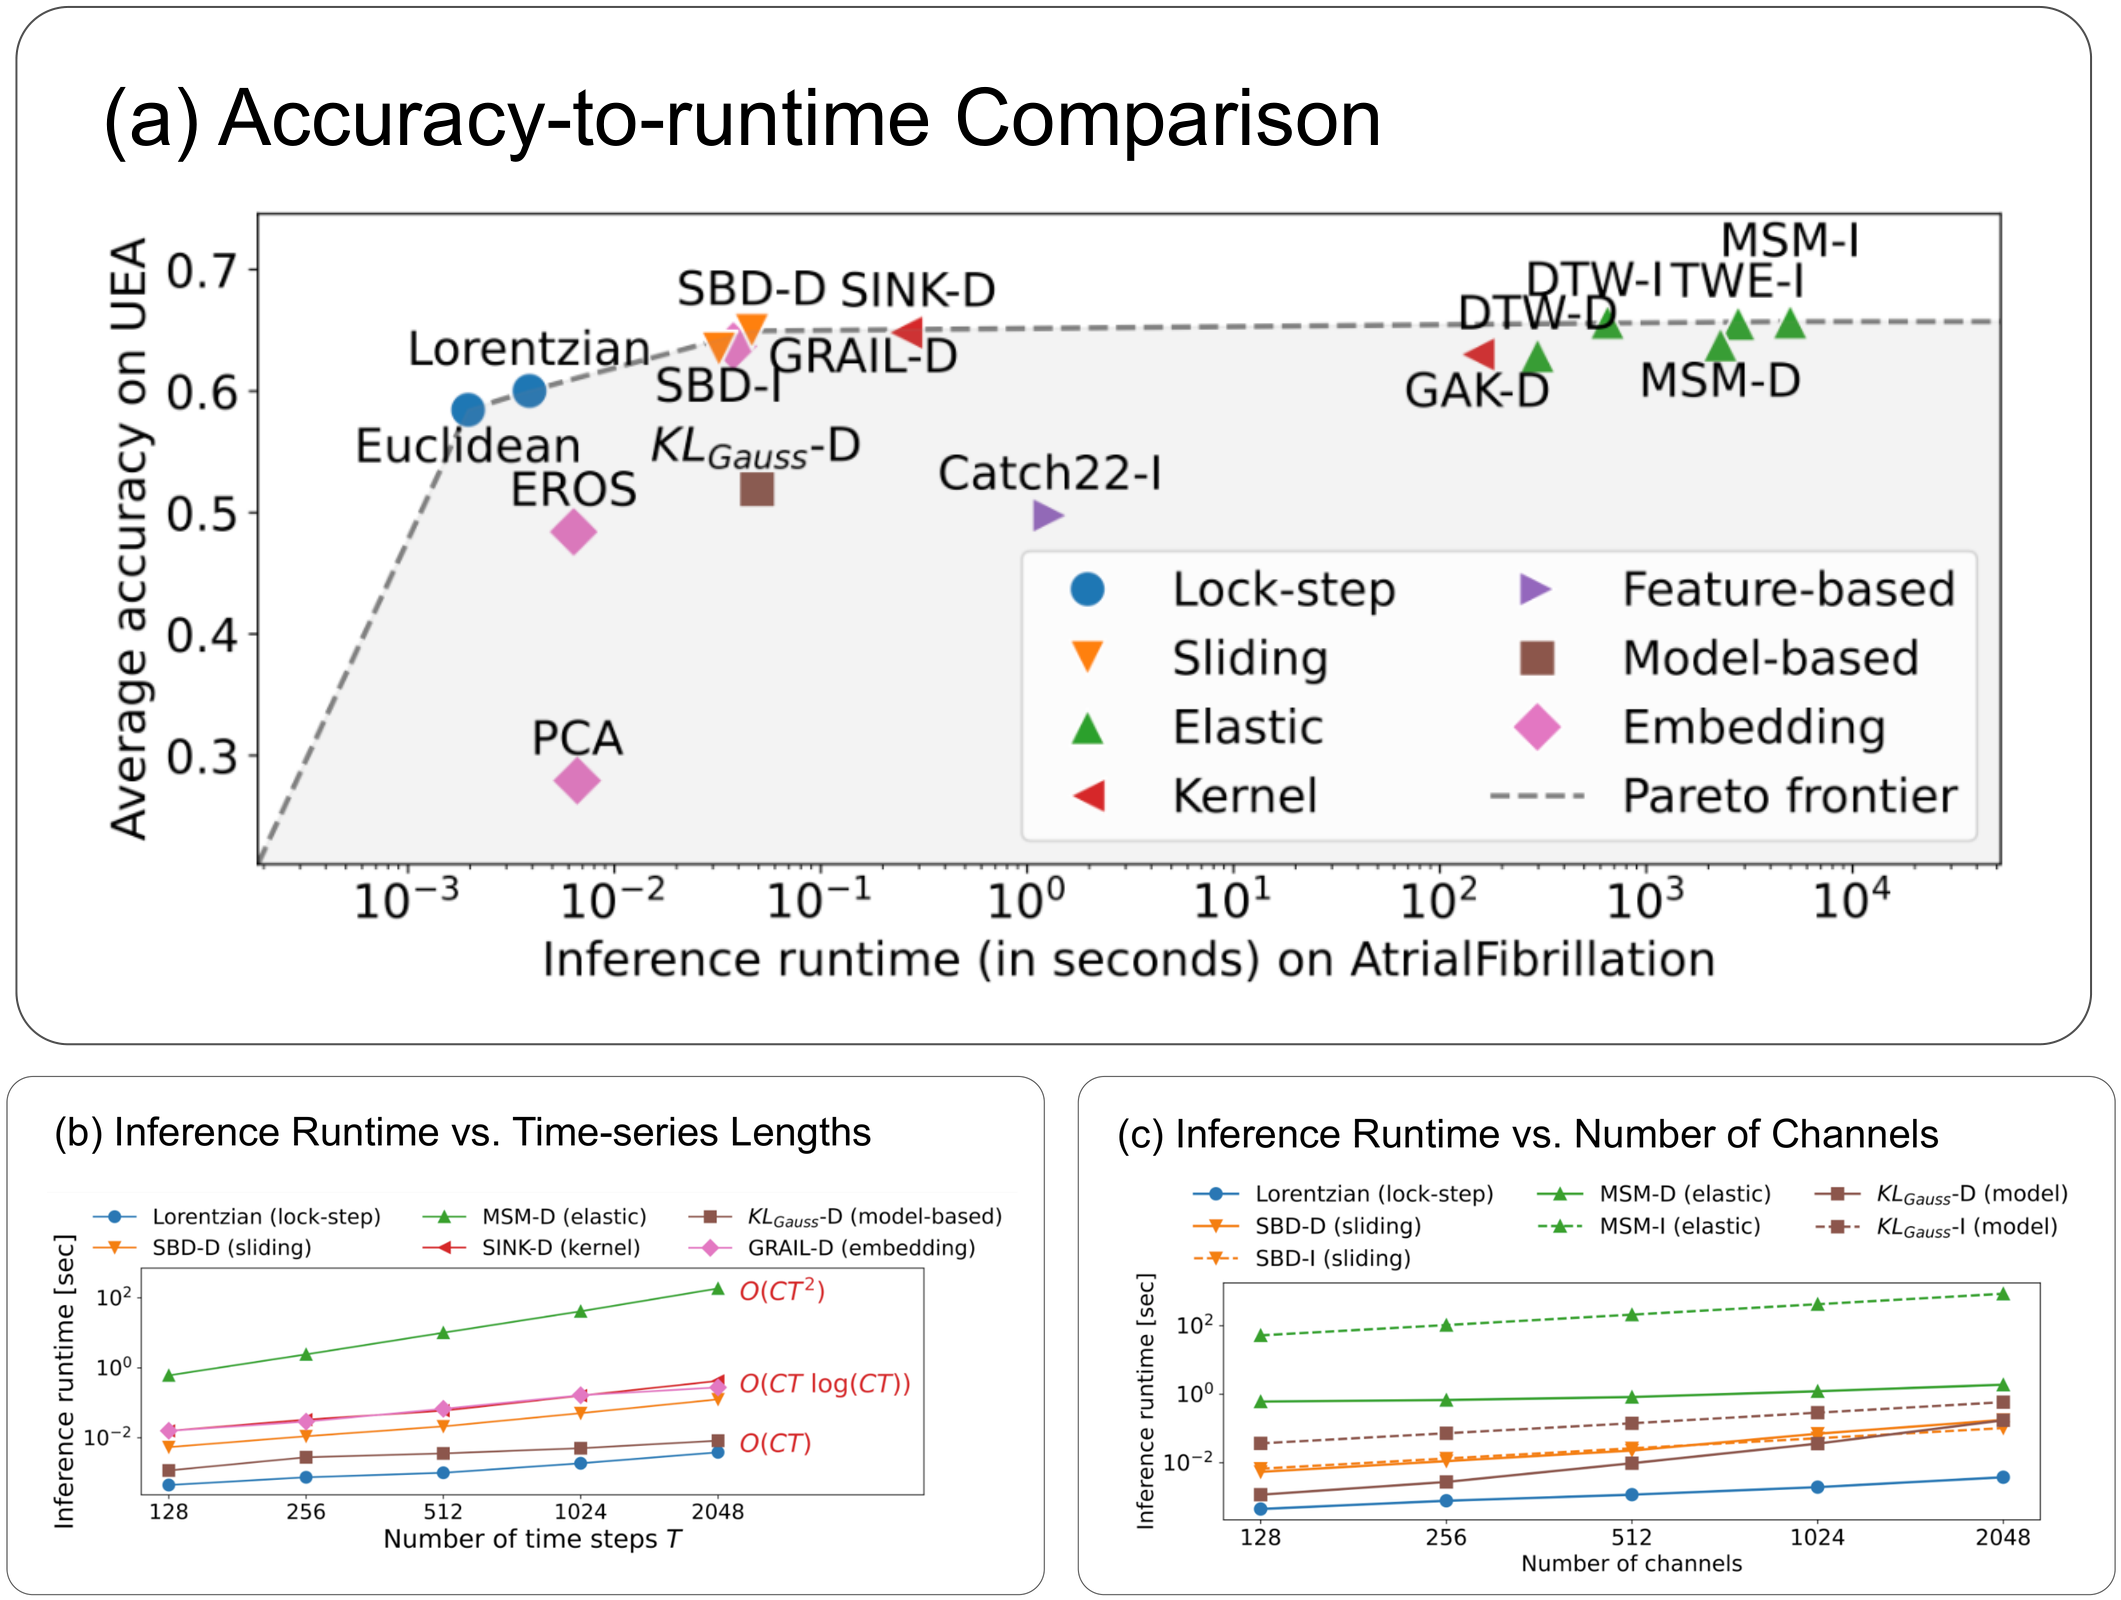
| Classification, clustering, or pattern matching, and you have no time to experiment | SBD-D (channel-dependent sliding) | Best accuracy-to-runtime trade-off; no parameters |
| Runtime is the hard constraint (sub-millisecond per comparison) | Lorentzian (lock-step) | Significantly more accurate than Euclidean at the same cost |
| Accuracy is all that matters and you have labeled data plus days of compute | MSM-I with tuned parameters (channel-independent elastic) | Only tuned MSM-I and TWE-I beat SBD-D significantly |
| You already picked an elastic measure and wonder about I versus D | Channel-independent | Independent alignment wins significantly for elastic measures |
| You picked anything other than an elastic measure | Channel-dependent | Dependent variants win significantly for sliding and kernel measures |
| Anomaly detection, where the distortion is the signal | Euclidean (lock-step) | Beat every sliding and elastic measure we tested |
The main findings behind that table:
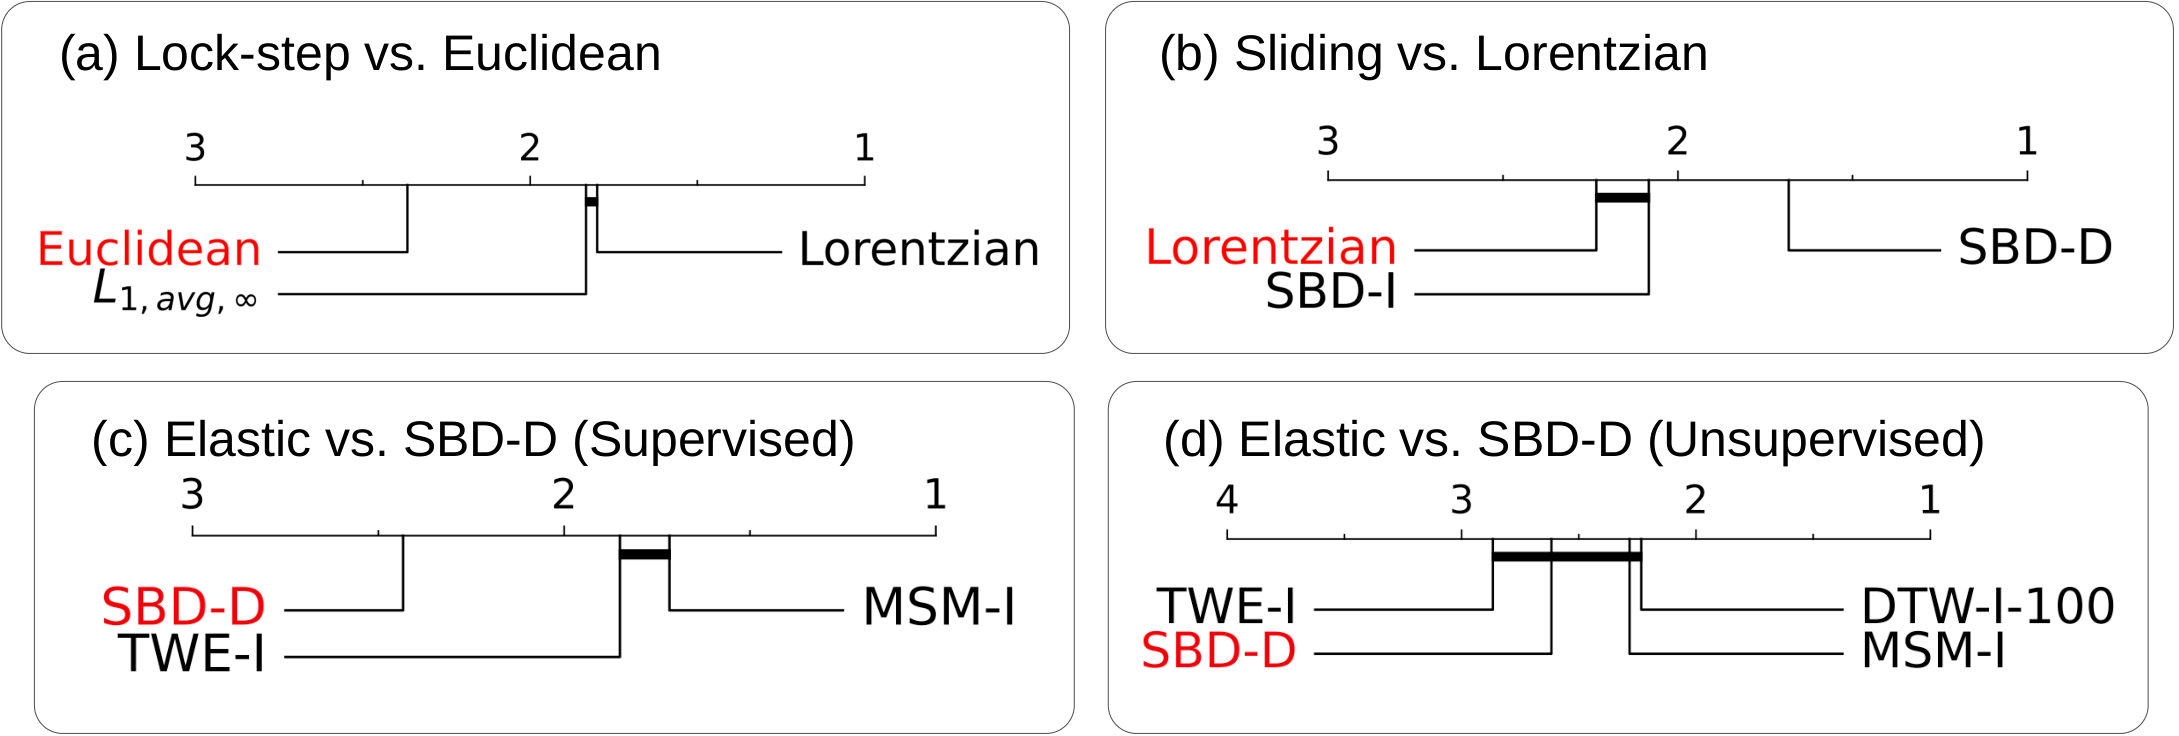
- Sliding measures are the sweet spot. SBD-D significantly outperformed the best lock-step measure on classification (average accuracy 0.68 versus 0.63 for Lorentzian) and on clustering (Rand index 0.75 versus 0.66 for Euclidean). On runtime, SBD-D took about 0.05 seconds on the AtrialFibrillation dataset, against 4982 seconds for MSM-I and 297 seconds for DTW-D: four to five orders of magnitude for roughly one percentage point of accuracy (0.65 versus about 0.66). SBD-D is O(CT log CT); elastic measures are O(CT^2).
- Newer elastic measures beat DTW, but only when tuned. With leave-one-out tuning, MSM-I and TWE-I were the only measures in the whole study that significantly beat SBD-D. With fixed default parameters, no elastic measure did, and DTW-I never did in either setting.
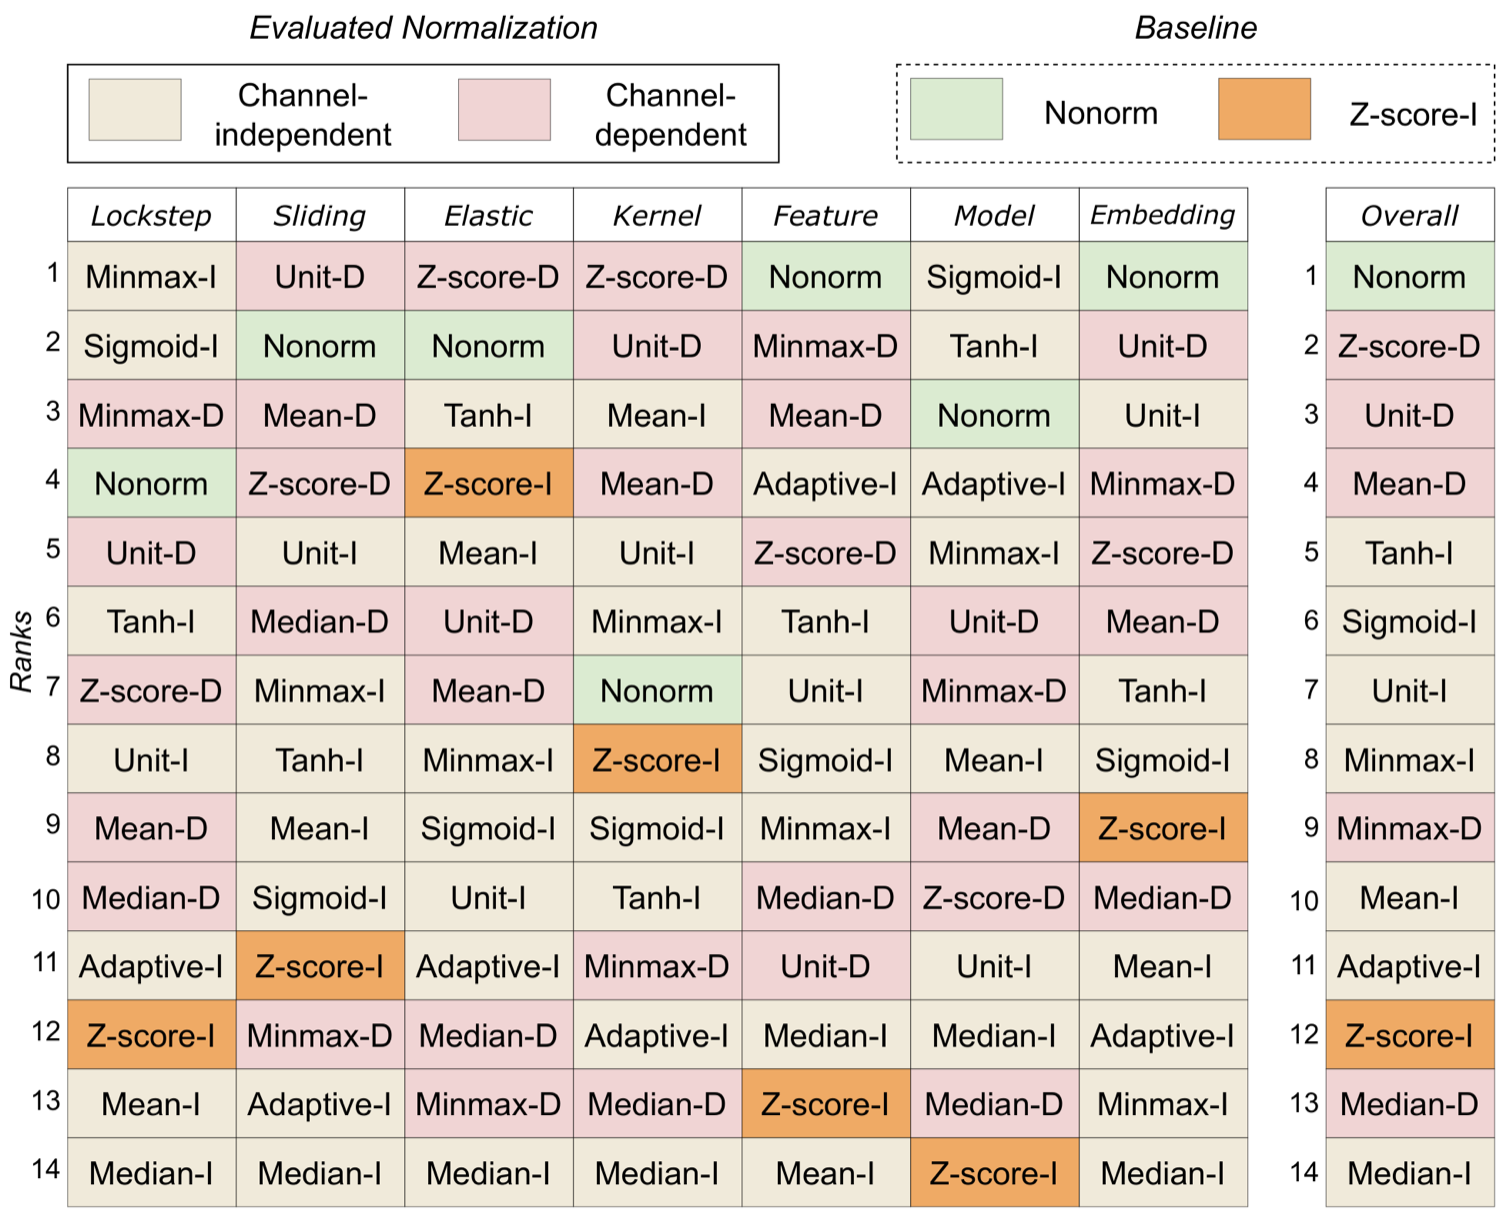
- Z-score is not automatically the right normalization. Per-channel z-score, the default in almost all multivariate work, ranked 12th out of 14 options in the overall meta-ranking. Not normalizing ranked first and was in the top four for every family except kernel measures. The Friedman-Nemenyi test found no normalization significantly better than the rest, which suggests the current methods, all direct extensions of univariate ones, are simply not designed for multivariate data.
- Independent channel treatment only helps elastic measures. Pooled over all measures, the two channel models tie. Per family: dependent wins significantly for sliding and kernel measures, independent wins significantly for elastic measures. Our explanation is that global shifts (what sliding measures fix) tend to hit all sensors at once, whereas local jitter (what elastic measures fix) tends to hit one channel at a time.
- Euclidean is not your best lock-step choice, except for anomaly detection. Lorentzian, L1, and L1,avg,inf all significantly beat Euclidean on classification. For anomaly detection with a 1-NN detector the ranking flipped: Euclidean significantly beat Lorentzian, SBD-D, DTW-D, DTW-I, and SBD-I. When you are looking for distortions, you do not want a measure that corrects them away.
- Deep-learning embeddings did not win. TS2Vec and GRAIL beat Euclidean, but none of the embedding, feature-based, model-based, or kernel measures matched SBD-D.
DTW versus Euclidean, in one paragraph
Because this is the comparison people actually search for: on multivariate classification, DTW-I and DTW-D scored higher than Euclidean on average, but DTW never significantly beat the parameter-free SBD-D, and it costs hours to days of compute on the larger UEA datasets. About to reach for DTW by default? Try SBD-D first. About to reach for Euclidean? Try Lorentzian.
Code: one lock-step and one elastic distance in Python
I used aeon 1.1.0 here because it ships multivariate versions of Euclidean, DTW, MSM, and SBD out of the box. Series are arrays of shape (n_channels, n_timepoints).
import numpy as np
from aeon.distances import euclidean_distance, msm_distance, sbd_distance

rng = np.random.default_rng(0)
x = rng.normal(size=(3, 100))  # 3 channels, 100 time points
y = rng.normal(size=(3, 100))

# Lock-step: Euclidean over all channels and time points.
# Channel-independent and channel-dependent variants are identical here.
d_lock = euclidean_distance(x, y)

# Elastic: Move-Split-Merge. independent=True gives MSM-I, the variant
# the study recommends when accuracy matters. c is the split/merge cost;
# c=0.5 was the default that worked best across the UEA archive.
d_msm_i = msm_distance(x, y, c=0.5, independent=True)
d_msm_d = msm_distance(x, y, c=0.5, independent=False)

# Sliding: aeon's multivariate SBD averages per-channel SBD, so this is
# SBD-I. For SBD-D (one shift shared by all channels, computed with a 2D
# FFT) see the MTSDistEval repository linked above.
d_sbd_i = sbd_distance(x, y, standardize=False)
Note the standardize=False: aeon z-scores each series inside sbd_distance by default, which is exactly the normalization the study found no benefit from on multivariate data.
Where to go next
- The full paper: A Structured Study of Multivariate Time-Series Distance Measures, SIGMOD 2025, doi:10.1145/3725258. The guidelines are in Section 6.
- The earlier, smaller version: Beyond the Dimensions, ICDE 2024 MulTiSa workshop. That study compared 12 measures on the UEA archive and found no single winner; the SIGMOD paper is what happened when we added the missing families, normalizations, tasks, and statistics.
- Background reading: A Survey on Time-Series Distance Measures, covering the 100+ measures and 7 categories the study draws from.
Cite this
@article{dhondt2025structured,
  author    = {d'Hondt, Jens E. and Li, Haojun and Yang, Fan and Papapetrou, Odysseas and Paparrizos, John},
  title     = {A Structured Study of Multivariate Time-Series Distance Measures},
  journal   = {Proceedings of the ACM on Management of Data},
  volume    = {3},
  number    = {3},
  articleno = {121},
  pages     = {1--29},
  year      = {2025},
  month     = jun,
  publisher = {Association for Computing Machinery},
  doi       = {10.1145/3725258}
}