<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://jensdhondt.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://jensdhondt.com/" rel="alternate" type="text/html" /><updated>2026-11-02T08:33:26+00:00</updated><id>https://jensdhondt.com/feed.xml</id><title type="html">Jens E. d’Hondt, PhD</title><subtitle>Jens d&apos;Hondt, postdoctoral scientist at the Barcelona Supercomputing Center: ML downscaling of atmospheric simulations and multivariate time-series search.</subtitle><author><name>Jens E. d&apos;Hondt, PhD</name><email>jens.dhondt@bsc.es</email></author><entry><title type="html">Beyond pairwise: finding multivariate correlations in large datasets</title><link href="https://jensdhondt.com/blog/multivariate-correlations-correlation-detective/" rel="alternate" type="text/html" title="Beyond pairwise: finding multivariate correlations in large datasets" /><published>2026-11-02T00:00:00+00:00</published><updated>2026-11-02T00:00:00+00:00</updated><id>https://jensdhondt.com/blog/multivariate-correlations-correlation-detective</id><content type="html" xml:base="https://jensdhondt.com/blog/multivariate-correlations-correlation-detective/"><![CDATA[<p><strong>TL;DR.</strong> A correlation matrix only tells you about pairs, and some of the most interesting relationships in a dataset only show up when you look at three or more variables together. During my PhD, Koen Minartz, Odysseas Papapetrou and I built <a href="https://correlationdetective.com/">Correlation Detective</a>, an exact algorithm that finds these multivariate correlations without enumerating the combinatorial search space, typically an order of magnitude faster than the state of the art and several orders faster than brute force. This post explains the idea in plain words, shows the numbers, and walks through running the library on your own data.</p>

<h2 id="why-pairwise-correlation-misses-things">Why pairwise correlation misses things</h2>

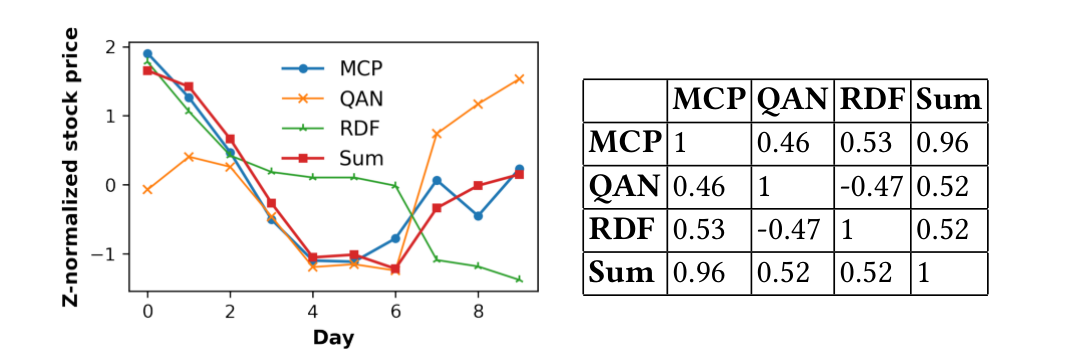
<p>Here is the example that opens our VLDB 2022 paper. Take the daily closing prices of three stocks on the Australian Securities Exchange, MCP, QAN and RDF. Pairwise, none of them look very related: MCP and QAN correlate at 0.46, MCP and RDF at 0.53, and QAN and RDF are negatively correlated at -0.47. But if you add QAN and RDF together, the resulting series tracks MCP with a correlation of 0.96. Looking only at pairs, you would never have found this. The same pattern shows up in fMRI data, where one brain region follows the average activity of two others, and in climate science, where a ternary correlation revealed a new teleconnection pattern.</p>

<figure>
  <a href="/images/blog/correlation-detective/stocks-example.png" target="_blank" rel="noopener"><img src="/images/blog/correlation-detective/stocks-example.png" alt="Line chart of z-normalized daily closing prices of MCP, QAN, RDF and the sum of QAN and RDF over ten days, next to their correlation matrix. The sum tracks MCP closely (correlation 0.96), while every pairwise correlation is between -0.47 and 0.53." style="width:100%" /></a>
  <figcaption>Three ASX stocks and their correlation matrix. No pair stands out, but QAN plus RDF follows MCP almost exactly. (Figure from the VLDB 2022 paper; click to enlarge.)</figcaption>
</figure>

<p>The two papers cover two families of multivariate correlation measures.</p>

<p>The first is <strong>bivariate correlation over aggregates</strong>. Take a set of vectors on the left, a set on the right, average each side element-wise, and compute an ordinary two-variable measure between the averages. With Pearson correlation this is often called multiple correlation (the MCP example is exactly this, with one vector on the left and two on the right; “tripoles” are the special case with sets of size 2 and 1). The journal paper also allows Euclidean similarity as the two-variable measure. These are two-sided: the answer says “this group behaves like that group”.</p>

<p>The second is <strong>one-sided measures on a single set</strong>. The <strong>multipole</strong> correlation asks how close a set of vectors is to being linearly dependent: one minus the smallest variance of any unit-norm linear combination of them, so it is 1 when some weighted combination is exactly constant. <strong>Total correlation</strong> is the information-theoretic cousin: the sum of the individual entropies minus the joint entropy, which measures how much redundancy the set contains as a whole. The VLDB 2022 paper handled multiple correlation and multipoles; the VLDB Journal paper generalized the machinery to four measures (Pearson, Euclidean similarity, multipole, total correlation).</p>

<h2 id="why-the-search-is-hard">Why the search is hard</h2>

<p>The problem is purely combinatorial. In a dataset of n vectors, finding all groups of up to p vectors means looking at roughly the sum of binomial coefficients C(n, 2) through C(n, p). With just 100 vectors, checking all ternary correlations already means over 1 million candidates. With 1000 vectors, all quaternary combinations amount to 1 trillion. Just generating that list is a problem, let alone computing a correlation for each entry.</p>

<p>What makes it worse is that apriori-style pruning, where you drop a group as soon as a subgroup fails the test, does not apply. The MCP example shows why: all pairwise correlations were mediocre, and the triple was excellent. Existing algorithms got around this by adding constraints to the definition, hard-coding assumptions about the query, or returning approximate results without guarantees.</p>

<h2 id="how-correlation-detective-prunes-the-space">How Correlation Detective prunes the space</h2>

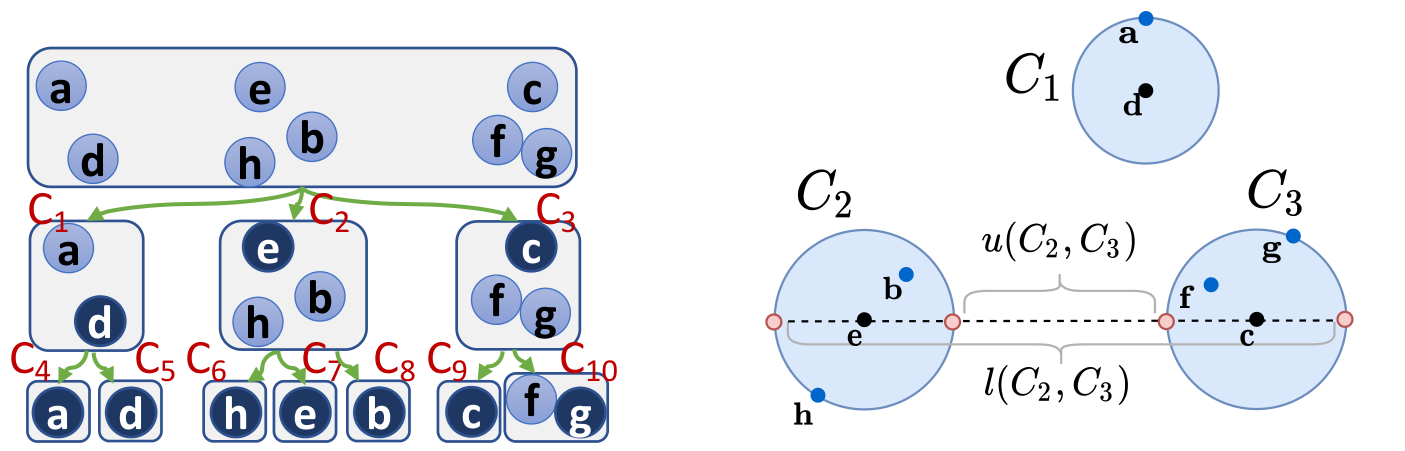
<p><strong>Bounds instead of exact values.</strong> The core observation is that all of these measures can be written as functions of pairwise quantities: pairwise Pearson correlations for multiple correlation and multipoles, dot products for Euclidean similarity, pairwise marginal and conditional entropies for total correlation. So if I know a lower and upper bound on every pairwise correlation between the members of some groups of vectors, I can bound the multivariate correlation of <em>any</em> combination drawn from those groups without computing a single one. For Pearson, the pairwise bounds come from geometry: after z-normalization, correlation is the cosine of the angle between two vectors, and the angle between two cluster centroids plus each cluster’s radius bounds the angle between any two members.</p>

<p><strong>Clustering-based search.</strong> Correlation Detective first clusters the vectors hierarchically (top-down K-means++, K around 10, a tree of three to four levels for 1000 vectors). It then enumerates combinations of <em>clusters</em> rather than vectors and computes the bounds for each. If the lower bound is above the threshold, every combination inside is an answer and gets added wholesale. If the upper bound is below it, the whole combination is discarded. Only if the threshold falls in between does the algorithm split the largest cluster and recurse. Because correlated vectors tend to land in the same clusters, most decisions happen high up in the tree, and clustering quality only affects speed, never correctness. Two refinements matter in practice: using the actual minimum and maximum pairwise correlations between cluster members instead of the worst-case geometric bounds narrows them by 50 to 90 percent and cuts runtime by about an order of magnitude, and a top-k variant seeds the running threshold with the k-th highest pairwise correlation and prioritizes promising branches. The same prioritization gives a progressive mode that returned around 80 percent of the answers in 10 percent of the time in the 2022 experiments, and over 90 percent in the journal experiments.</p>

<figure>
  <a href="/images/blog/correlation-detective/cluster-bounds.png" target="_blank" rel="noopener"><img src="/images/blog/correlation-detective/cluster-bounds.png" alt="Left: a three-level cluster tree over eight vectors a to h, with root clusters C1, C2 and C3 split into sub-clusters C4 to C10. Right: three clusters drawn as circles around their centroids, with the closest and farthest possible distances between members of C2 and C3 marked as u and l." style="width:100%" /></a>
  <figcaption>Left: the cluster hierarchy that the search walks down, splitting a cluster only when a combination is indecisive. Right: how the centroid distance and the cluster radii bound the correlation between any two members of C2 and C3. (Figure from the VLDB 2022 paper; click to enlarge.)</figcaption>
</figure>

<p><strong>Keeping results fresh on streams.</strong> The bounds of a cluster combination depend on only two pairs of vectors per cluster pair: the ones that determine the minimum and maximum pairwise correlation (the “extrema pairs”). CDStream stores every decisive cluster combination in an index keyed by those pairs. When a new value arrives, the index says which extrema pairs might have changed; if they are still valid, nothing else needs checking. Updates are processed in batches (in the journal version, configurable epochs inside a sliding window, trading freshness for throughput). Because a burst of updates can invalidate so much of the index that recomputing from scratch is cheaper, CDHybrid fits a small online regression on arrival counts and execution times and switches between CDStream and plain CD automatically.</p>

<h2 id="results">Results</h2>

<p>Thresholds and query patterns differ per row, so read across, not down.</p>

<table>
  <thead>
    <tr>
      <th>Dataset</th>
      <th>Size</th>
      <th>Baseline</th>
      <th>What happened</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>fMRI (VLDB 2022)</td>
      <td>9,700 series x 5,470 obs.</td>
      <td>CONTRa (tripoles, min. jump 0.1)</td>
      <td>CONTRa did not finish in 24 h; CD took 17,027 s for the same results at threshold 0, and 458 s at threshold 0.9</td>
    </tr>
    <tr>
      <td>SLP (VLDB 2022)</td>
      <td>171 series x 108 obs.</td>
      <td>CoMEtExtended (multipole, size 4)</td>
      <td>CoMEtExtended one to two (rho=0) or two to three (rho=0.02) orders of magnitude slower than CD, and returned fewer results</td>
    </tr>
    <tr>
      <td>fMRI (VLDB 2022)</td>
      <td>subsets up to 9,700 series</td>
      <td>Exhaustive search</td>
      <td>Several orders of magnitude; exhaustive runs interrupted after 20 h</td>
    </tr>
    <tr>
      <td>fMRI (VLDBJ)</td>
      <td>237 and 509 series</td>
      <td>Four in-memory DBMS, SQL for PC(1,3)</td>
      <td>CD 2.70 s and 16.63 s; DBMS1 168.86 s and 5,138.61 s; the other three timed out at 8 h</td>
    </tr>
    <tr>
      <td>Stocks (VLDBJ)</td>
      <td>subsets up to 12,800 of 28,678 stocks</td>
      <td>Two exhaustive baselines (OPT, UNOPT)</td>
      <td>Baselines hit the 8 h limit for all four measures; CD’s runtime grows at a much slower rate</td>
    </tr>
    <tr>
      <td>Stocks stream (VLDB 2022)</td>
      <td>1,000 stocks, window 2,000</td>
      <td>CD re-run per batch</td>
      <td>CDStream needs a few milliseconds per batch for small patterns, about an order of magnitude less than CD</td>
    </tr>
  </tbody>
</table>

<h2 id="running-correlation-detective">Running Correlation Detective</h2>

<p>The library is Java 11+, GPL-3.0, at <a href="https://github.com/CorrelationDetective/library">github.com/CorrelationDetective/library</a>. It implements the static algorithm; the streaming code is in the <a href="https://github.com/CorrelationDetective/public">research repository</a>. Install via Maven:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">&lt;dependency&gt;</span>
    <span class="nt">&lt;groupId&gt;</span>io.github.correlationdetective<span class="nt">&lt;/groupId&gt;</span>
    <span class="nt">&lt;artifactId&gt;</span>CorrelationDetective<span class="nt">&lt;/artifactId&gt;</span>
    <span class="nt">&lt;version&gt;</span>1.0<span class="nt">&lt;/version&gt;</span>
<span class="nt">&lt;/dependency&gt;</span>
</code></pre></div></div>

<p>or build from source:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/CorrelationDetective/library.git
<span class="nb">cd </span>library
mvn clean <span class="nb">install</span>
</code></pre></div></div>

<p>Input is a CSV in row-major (first row holds vector names, first column dimension names) or column-major order. A threshold query for the stock example’s pattern, one vector on the left and up to two on the right:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">String</span> <span class="n">inputPath</span> <span class="o">=</span> <span class="s">"/path/to/your/dataset.csv"</span><span class="o">;</span>
<span class="nc">SimEnum</span> <span class="n">simMetricName</span> <span class="o">=</span> <span class="nc">SimEnum</span><span class="o">.</span><span class="na">PEARSON_CORRELATION</span><span class="o">;</span> <span class="c1">// also MULTIPOLE, TOTAL_CORRELATION, EUCLIDEAN_SIMILARITY, ...</span>
<span class="kt">int</span> <span class="n">maxPLeft</span> <span class="o">=</span> <span class="mi">1</span><span class="o">;</span>
<span class="kt">int</span> <span class="n">maxPRight</span> <span class="o">=</span> <span class="mi">2</span><span class="o">;</span>

<span class="nc">CorrelationDetective</span> <span class="n">cd</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">CorrelationDetective</span><span class="o">(</span><span class="n">inputPath</span><span class="o">,</span> <span class="n">simMetricName</span><span class="o">,</span> <span class="n">maxPLeft</span><span class="o">,</span> <span class="n">maxPRight</span><span class="o">);</span>
<span class="n">cd</span><span class="o">.</span><span class="na">runParameters</span><span class="o">.</span><span class="na">setQueryType</span><span class="o">(</span><span class="nc">QueryTypeEnum</span><span class="o">.</span><span class="na">THRESHOLD</span><span class="o">);</span> <span class="c1">// default is TOPK with topK = 100</span>
<span class="n">cd</span><span class="o">.</span><span class="na">runParameters</span><span class="o">.</span><span class="na">setTau</span><span class="o">(</span><span class="mf">0.7</span><span class="o">);</span>

<span class="nc">ResultSet</span> <span class="n">rs</span> <span class="o">=</span> <span class="n">cd</span><span class="o">.</span><span class="na">run</span><span class="o">();</span>
<span class="nc">List</span><span class="o">&lt;</span><span class="nc">ResultTuple</span><span class="o">&gt;</span> <span class="n">resultTuples</span> <span class="o">=</span> <span class="n">rs</span><span class="o">.</span><span class="na">getResultTuples</span><span class="o">();</span>
<span class="n">rs</span><span class="o">.</span><span class="na">saveAsCSV</span><span class="o">(</span><span class="s">"/path/to/output/results.csv"</span><span class="o">);</span>

<span class="nc">StatBag</span> <span class="n">statBag</span> <span class="o">=</span> <span class="n">cd</span><span class="o">.</span><span class="na">getStatBag</span><span class="o">();</span>
<span class="n">statBag</span><span class="o">.</span><span class="na">saveAsJson</span><span class="o">(</span><span class="s">"/path/to/output/stats.json"</span><span class="o">);</span>
</code></pre></div></div>

<p>Other useful knobs in <code class="language-plaintext highlighter-rouge">RunParameters</code> are <code class="language-plaintext highlighter-rouge">setMinJump</code>, <code class="language-plaintext highlighter-rouge">setIrreducibility</code>, <code class="language-plaintext highlighter-rouge">setTopK</code>, and <code class="language-plaintext highlighter-rouge">setNVectors</code> to try a prefix of the data first; <code class="language-plaintext highlighter-rouge">PARAMETERS.md</code> in the repository lists all of them. The parameter table also lists <code class="language-plaintext highlighter-rouge">SPEARMAN_CORRELATION</code> and <code class="language-plaintext highlighter-rouge">MANHATTAN_SIMILARITY</code>, which are not evaluated in the papers.</p>

<h2 id="what-i-would-use-it-for-today">What I would use it for today</h2>

<ul>
  <li><strong>Atmospheric and climate data.</strong> In my current work on downscaling atmospheric simulations, I look at hundreds of gridded variables at once. Asking which combinations of two or three upstream variables jointly track a target quantity is exactly a PC(1,2) query.</li>
  <li><strong>Finding baskets in financial data.</strong> An asset that tracks a combination of others is interesting for hedging and for spotting redundancy in a portfolio. The streaming variant is what you want to keep up with minute-level prices.</li>
  <li><strong>Monitoring many sensors or servers.</strong> Prior work used multivariate correlation across server requests to detect denial-of-service attacks. Any setting with thousands of streams where a single sensor is only explained by a combination of others fits.</li>
</ul>

<p>The <a href="https://correlationdetective.com/">Correlation Detective website</a> has more of these scenarios, from fMRI and genomics to flash trading and weather sensor networks, plus a <a href="https://www.youtube.com/watch?v=U7z4uyonixk">two-minute video introduction</a> and an <a href="https://correlationdetective.com/app/">interactive demo</a> of CDStream on NYSE trade and quote data.</p>

<h2 id="links">Links</h2>

<ul>
  <li>Paper page: <a href="/publication/cd_conf_2022">Multivariate correlations discovery in static and streaming data</a> (VLDB 2022, <a href="https://www.vldb.org/pvldb/vol15/p1266-papapetrou.pdf">open PDF</a>)</li>
  <li>Paper page: <a href="/publication/cd_journal_2024">Efficient detection of multivariate correlations with different correlation measures</a> (The VLDB Journal, 2024, <a href="https://link.springer.com/article/10.1007/s00778-023-00815-y">open access</a>)</li>
  <li>Project website: <a href="https://correlationdetective.com/">correlationdetective.com</a>, with a <a href="https://www.youtube.com/watch?v=U7z4uyonixk">video introduction</a>, an <a href="https://correlationdetective.com/app/">interactive demo</a> and more application scenarios</li>
  <li>Library and docs: <a href="https://github.com/CorrelationDetective/library">GitHub</a></li>
  <li>Talk: <a href="/talks/2022-09-09-cd-vldb">VLDB 2022 presentation in Sydney</a>, with slides and the recording</li>
</ul>

<h2 id="cite-this">Cite this</h2>

<div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">minartz2022multivariate</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">{Minartz, Koen and d'Hondt, Jens E. and Papapetrou, Odysseas}</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">{Multivariate Correlations Discovery in Static and Streaming Data}</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">{Proceedings of the VLDB Endowment}</span><span class="p">,</span>
  <span class="na">volume</span>  <span class="p">=</span> <span class="s">{15}</span><span class="p">,</span>
  <span class="na">number</span>  <span class="p">=</span> <span class="s">{6}</span><span class="p">,</span>
  <span class="na">pages</span>   <span class="p">=</span> <span class="s">{1266--1278}</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">{2022}</span><span class="p">,</span>
  <span class="na">doi</span>     <span class="p">=</span> <span class="s">{10.14778/3514061.3514072}</span>
<span class="p">}</span>

<span class="nc">@article</span><span class="p">{</span><span class="nl">dhondt2024efficient</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">{d'Hondt, Jens E. and Minartz, Koen and Papapetrou, Odysseas}</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">{Efficient detection of multivariate correlations with different correlation measures}</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">{The VLDB Journal}</span><span class="p">,</span>
  <span class="na">volume</span>  <span class="p">=</span> <span class="s">{33}</span><span class="p">,</span>
  <span class="na">pages</span>   <span class="p">=</span> <span class="s">{481--505}</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">{2024}</span><span class="p">,</span>
  <span class="na">doi</span>     <span class="p">=</span> <span class="s">{10.1007/s00778-023-00815-y}</span>
<span class="p">}</span>
</code></pre></div></div>]]></content><author><name>Jens E. d&apos;Hondt, PhD</name><email>jens.dhondt@bsc.es</email></author><category term="correlation" /><category term="time series" /><category term="data mining" /><summary type="html"><![CDATA[How Correlation Detective finds groups of three to five correlated time series in large datasets, orders of magnitude faster than brute force.]]></summary></entry><entry><title type="html">Searching multivariate time series when only some channels matter</title><link href="https://jensdhondt.com/blog/ms-index-multivariate-subsequence-search/" rel="alternate" type="text/html" title="Searching multivariate time series when only some channels matter" /><published>2026-10-01T00:00:00+00:00</published><updated>2026-10-01T00:00:00+00:00</updated><id>https://jensdhondt.com/blog/ms-index-multivariate-subsequence-search</id><content type="html" xml:base="https://jensdhondt.com/blog/ms-index-multivariate-subsequence-search/"><![CDATA[<p><strong>TL;DR.</strong> MS-Index is an exact index for top-k subsequence search on multivariate time series under Euclidean distance, and it lets you pick which channels the query should look at when you run the query, not when you build the index. It summarises every subsequence with a handful of data-adapted DFT coefficients per channel, stores those in one R-tree, and uses two probes of the tree plus MASS to prune over 99% of candidates while still returning the correct answer. Across 34 datasets it was one to two orders of magnitude faster than the state of the art, for both raw and normalised subsequences, and its query time grows sublinearly with the number of query channels.</p>

<h2 id="the-problem">The problem</h2>

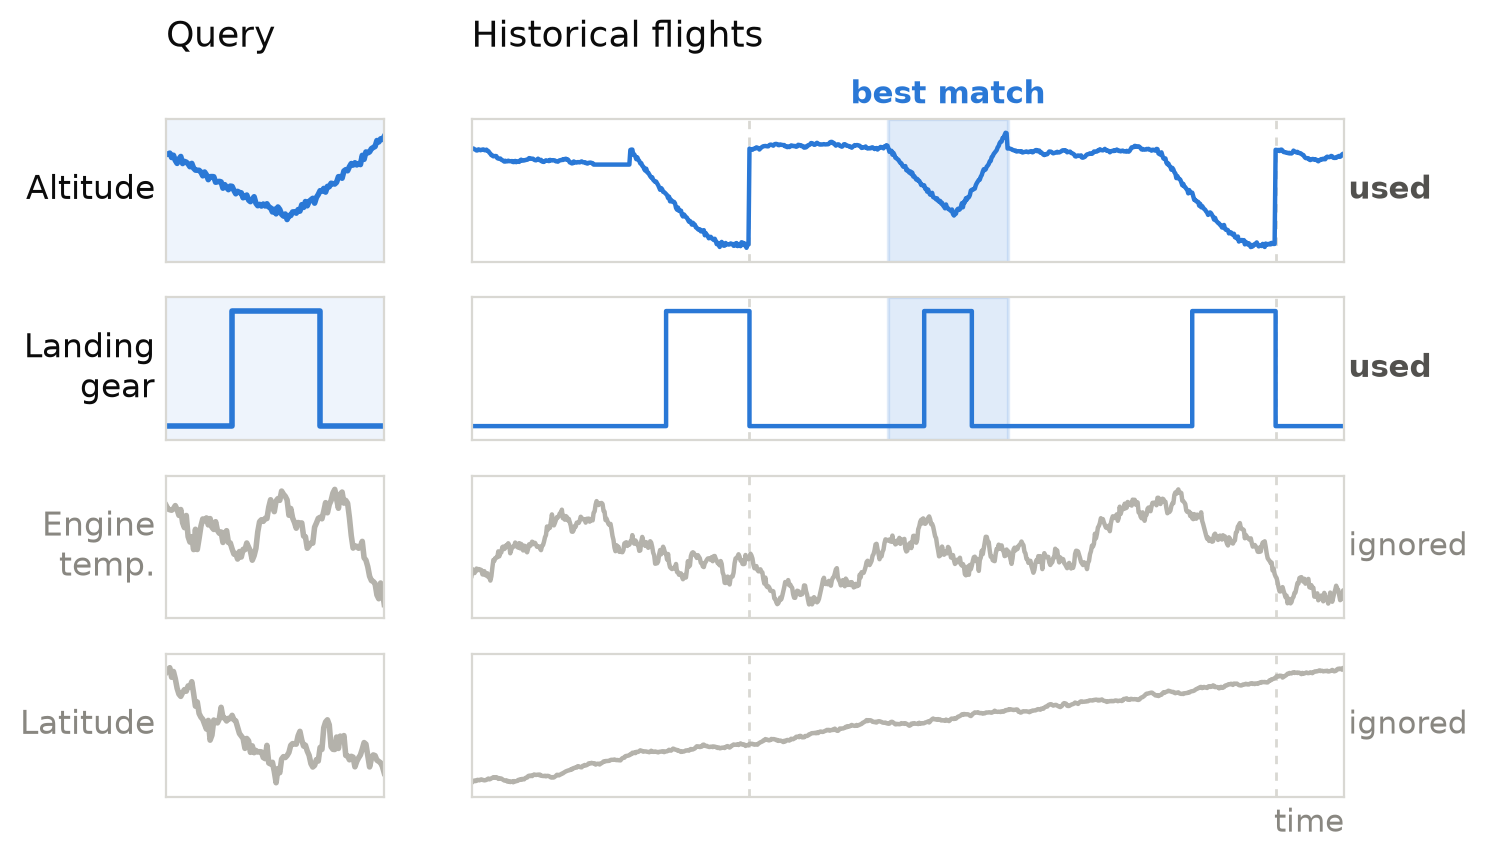
<p>Most sensor data these days is multivariate: many channels recorded together about the same object. An airplane logs altitude, latitude, landing gear state, engine parameters, and much more. Suppose an engineer is investigating a failed landing they suspect was caused by the landing gear. They take the short window of the failed landing and ask: where in our historical data did something similar happen?</p>

<p>That is a <strong>subsequence search</strong> query: given a query pattern of some length, find the k windows of the same length, anywhere in a large collection of long time series, that look most like it. The catch is which channels count. For the landing gear question, altitude and landing gear matter and engine temperature does not. For a question about a manoeuvre, a different set matters. The channel set is a property of the <em>question</em>, so it is only known at query time. In the paper we call this <strong>ad-hoc channel selection</strong>.</p>

<figure>
  <a href="/images/blog/ms-index/problem.png" target="_blank" rel="noopener"><img src="/images/blog/ms-index/problem.png" alt="Four channels of flight data: altitude, landing gear, engine temperature and latitude. A short query window of a failed landing on the left; a long historical record on the right with the best-matching window highlighted on the altitude and landing gear channels only. Engine temperature and latitude are greyed out and marked ignored." style="width:100%" /></a>
  <figcaption>Ad-hoc channel selection. The engineer picks the window of a failed landing and decides, for this question, that only altitude and landing gear count. The best match in the historical data is the window closest on those two channels; engine temperature and latitude play no part. Another question would pick other channels, against the same index. (Illustration with synthetic data; click to enlarge.)</figcaption>
</figure>

<p>Existing work does not cover this. Univariate indexes (ST-index, KV-match, DSTree, iSAX) handle one channel. The few multivariate indexes either match whole time series rather than subsequences, bake a fixed channel set into the index, or need a distance threshold per channel, which is not what a k-NN query looks like. You can glue per-channel univariate indexes together with a threshold-algorithm wrapper (we did, for baselines), but its pruning power turns out to be poor.</p>

<h2 id="how-ms-index-works">How MS-Index works</h2>

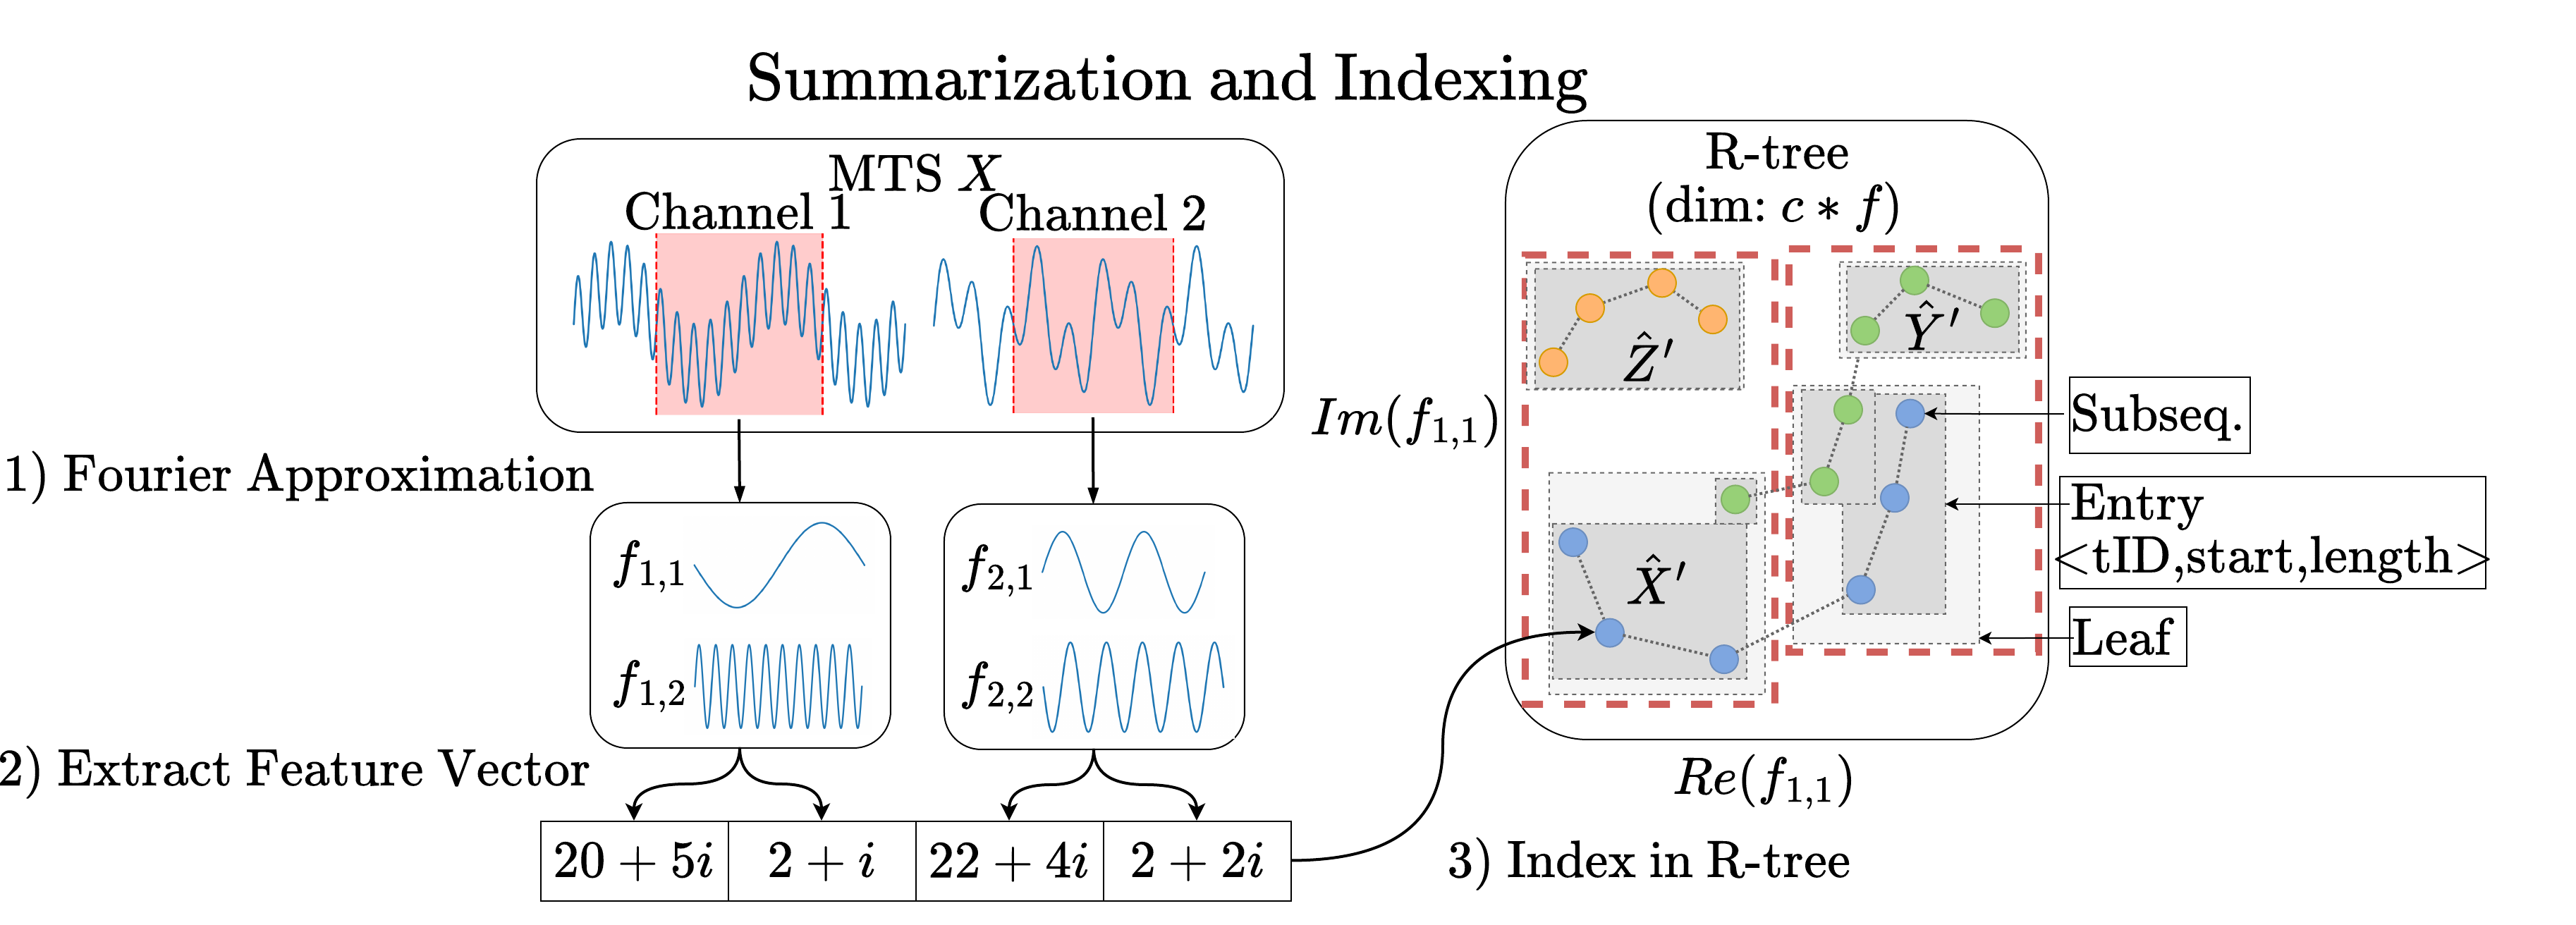
<p>MS-Index has three pieces: a summary of every subsequence, an R-tree over those summaries, and a two-pass query that uses MASS for exact distances. None is new on its own. What is new is combining them so that the result works over any subset of channels, stays exact, and gets faster rather than slower as you add channels.</p>

<figure>
  <a href="/images/blog/ms-index/summarization.png" target="_blank" rel="noopener"><img src="/images/blog/ms-index/summarization.png" alt="Diagram of the MS-Index pipeline: each channel of a multivariate time series is approximated with a few Fourier coefficients, the coefficients are flattened into one feature vector, and the vectors are stored in an R-tree whose leaves group time-neighbouring subsequences." style="width:100%" /></a>
  <figcaption>Summarising and indexing. Every subsequence is reduced to a few DFT coefficients per channel, flattened into one feature vector, and stored in a single R-tree where time-neighbouring subsequences share an entry. (Figure from the paper; click to enlarge.)</figcaption>
</figure>

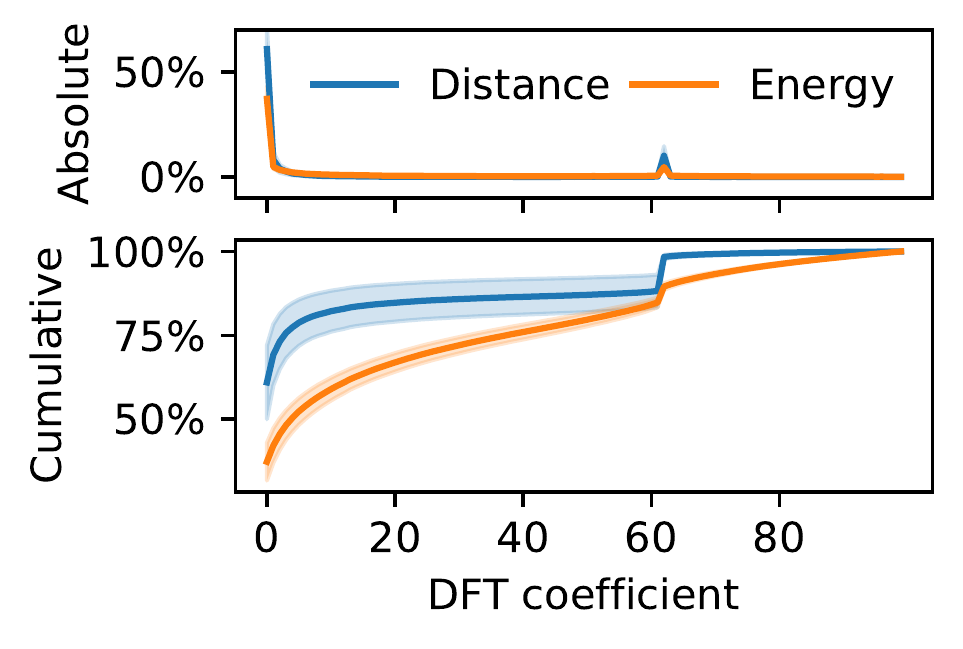
<p><strong>Summarising subsequences with the right DFT coefficients.</strong> The standard trick for Euclidean distance is to take the discrete Fourier transform and keep only a few coefficients; the distance between two truncated DFTs is a lower bound on the true distance, so it can be used to prune. The usual choice is the first f coefficients, since low frequencies carry most of the energy. Real data disagreed with that on two counts. The highest-energy coefficients are not always the first ones (a temperature dataset had a jump at the 62nd coefficient, from the daily cycle). And the coefficients that matter for <em>distances between</em> series are more concentrated than the ones that carry energy: on that dataset the top 5 coefficients covered about 90% of the distance but only about 60% of the energy. So MS-Index takes a sample of subsequences (typically 100), measures how much each coefficient of each channel contributes to pairwise distances, and keeps the top coefficients per channel until a target share of the distance is covered (60% worked best). These are flattened into one feature vector of length channels times f.</p>

<figure>
  <img src="/images/blog/ms-index/coefficients.png" alt="Two stacked line charts over DFT coefficient index on a temperature channel. Top: absolute share of total distance and energy per coefficient. Bottom: cumulative share. Distance is concentrated in fewer coefficients than energy, with a second spike near coefficient 62." style="width:55%;display:block;margin:0 auto" />
  <figcaption>Distance versus energy across DFT coefficients on a temperature channel. A handful of coefficients cover most of the distance, but not most of the energy, and the important ones are not simply the first few (note the jump near coefficient 62, the daily cycle). (Figure from the paper.)</figcaption>
</figure>

<p><strong>One R-tree, with neighbouring windows grouped.</strong> All feature vectors go into a single R-tree, built bottom-up. A series of length m has about m subsequences, so the naive entry count is huge, but consecutive windows overlap almost entirely and land close together in feature space. After building the leaves, MS-Index merges runs of time-neighbouring subsequences from the same series into one entry: a bounding rectangle plus a start and end offset. That merges around 8 to 50 subsequences per entry, and lets one lower-bound computation prune a whole run of windows at once.</p>

<p><strong>Arbitrary channel subsets.</strong> This is almost free, and it is why there is one tree rather than one per channel. The DFT lower bound holds for any subset of coefficients, so dropping the dimensions of channels you do not care about keeps it valid. An R-tree can answer a query on a subset of its dimensions natively, so at query time we project the query onto the dimensions of the chosen channels and search. The index never needs to know in advance which channels will be asked for.</p>

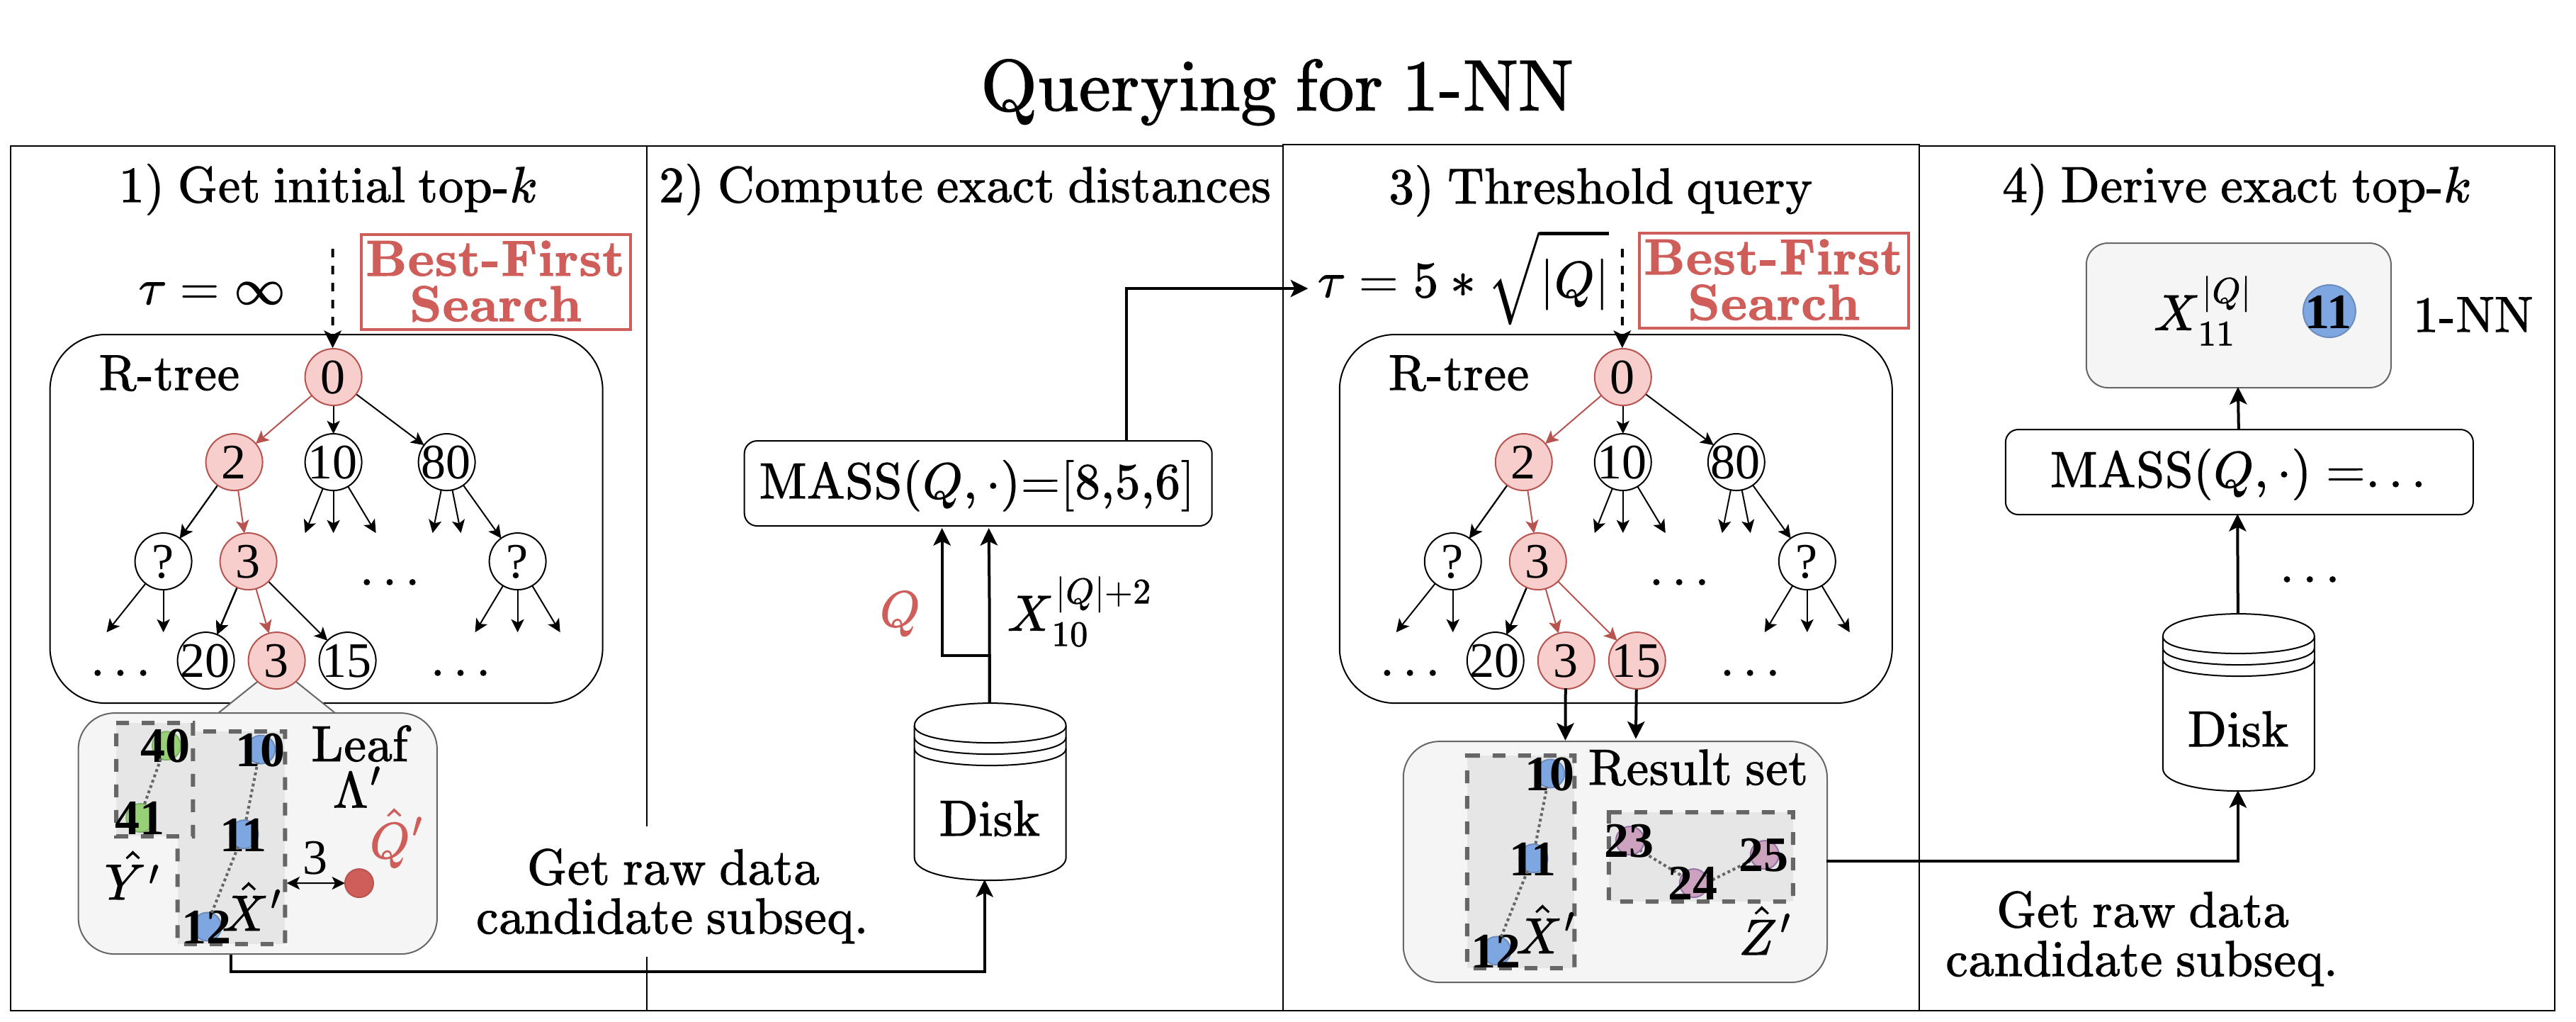
<p><strong>Staying exact with two probes.</strong> The first probe is a best-first search for the k entries with the smallest lower bound, followed by exact distances with MASS (the convolution-based algorithm that gives the distance from the query to every window of a series in O(m log m)). The k-th smallest exact distance becomes a threshold. The second probe is a range query with that threshold, again followed by exact MASS distances. Since every lower bound sits below the true distance, no true neighbour can fall outside the range, so the result is exact (Lemma 3.1 in the paper). Three tweaks sharpen the pruning: a pivot-based correction term for the distance the kept coefficients miss (about 2x faster queries), variance-weighted R-tree partitioning (1.5 to 3x), and distance browsing so the second probe continues where the first stopped. Combined, about a factor of 4.</p>

<figure>
  <a href="/images/blog/ms-index/querying.png" target="_blank" rel="noopener"><img src="/images/blog/ms-index/querying.png" alt="Four-step diagram of a 1-NN query: best-first search of the R-tree for an initial candidate, exact MASS distances on the raw data, a threshold query using the best distance found, and a final MASS pass to return the exact nearest neighbour." style="width:100%" /></a>
  <figcaption>Answering a 1-NN query in two probes. A best-first search gives an initial candidate, whose exact distance becomes the threshold; a second range query with that threshold collects every window that could still be closer, and exact distances on those give the answer. (Figure from the paper; click to enlarge.)</figcaption>
</figure>

<p><strong>Why more channels makes it faster.</strong> Each added channel adds a few dimensions, which costs a little per node visited, but it also makes the lower bounds more discriminative. On the 1024-channel DuckDuckGeese dataset, going from 8 to 16 query channels cut query time from 8.4 to 4.4 ms, and it grew only slowly after that. The share of R-tree nodes pruned rose from 70.5% at 16 channels to 97.9% at 1024 (raw subsequences). The per-channel baselines grow almost linearly, because they union per-channel results.</p>

<h2 id="what-the-experiments-showed">What the experiments showed</h2>

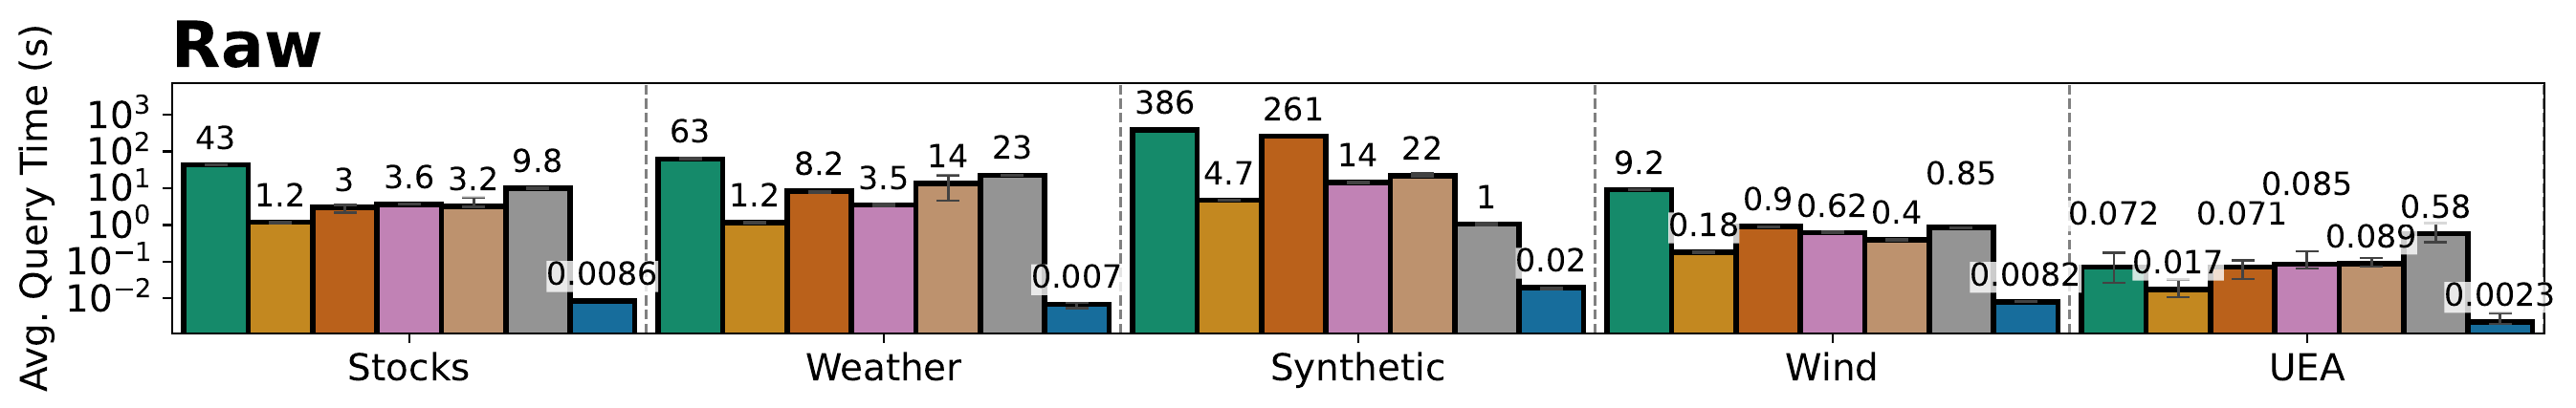
<p>We ran on 34 datasets: Stocks (28,678 stocks, 5 channels, query length 730 days), Weather (13,545 sensors, 4 channels), Wind (one 432,000-point turbine series, 10 channels), a 64-channel synthetic set, and the 30 UEA archive datasets. Baselines were MULISSE (our earlier multivariate index), MASS, brute force, and multivariate wrappers of ST-index, KV-match and DSTree. All single-threaded, in memory, Java 11.</p>

<figure>
  <a href="/images/blog/ms-index/query-time.png" target="_blank" rel="noopener"><img src="/images/blog/ms-index/query-time.png" alt="Bar chart of average query time in seconds on a log scale for seven algorithms on the Stocks, Weather, Synthetic, Wind and UEA datasets with raw subsequences. MS-Index, the last bar in each group, is the lowest in all five." style="width:100%" /></a>
  <img src="/images/blog/ms-index/query-time-legend.png" alt="Legend: brute force, MASS, DSTree, ST-index, KV-match, MULISSE, MS-Index" style="width:90%;margin-top:.5em" />
  <figcaption>Average query time per dataset (raw subsequences, log scale, bars in the order of the legend). MS-Index is the rightmost bar in each group. (Figure from the paper; click to enlarge.)</figcaption>
</figure>

<table>
  <thead>
    <tr>
      <th>Setting</th>
      <th>Closest competitor</th>
      <th>MS-Index speedup</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Stocks, raw, all channels</td>
      <td>MASS</td>
      <td>over 100x (over 1000x vs the other indexes)</td>
    </tr>
    <tr>
      <td>Wind, raw (very long series)</td>
      <td>MASS</td>
      <td>about 22x (about 100x vs the others)</td>
    </tr>
    <tr>
      <td>30 UEA datasets, raw</td>
      <td>MASS</td>
      <td>5 to 7x</td>
    </tr>
    <tr>
      <td>Weather and Synthetic, raw</td>
      <td>MASS or DSTree</td>
      <td>1 to 2 orders of magnitude</td>
    </tr>
    <tr>
      <td>Normalised subsequences</td>
      <td>MASS</td>
      <td>“similar patterns” to raw per the paper; pruning weakens slowly as channels grow</td>
    </tr>
  </tbody>
</table>

<p>Median pruning was 99% of subsequences. The per-channel wrappers pruned only 52% (ST-index), 65% (KV-match) and 46% (DSTree) on Stocks, and MULISSE 9%. Query time is independent of query length, since MASS’s cost depends on the series length, not the query.</p>

<h2 id="when-to-use-it-and-when-not-to">When to use it, and when not to</h2>

<p>Use MS-Index if you run many k-NN subsequence queries against a fixed collection, need exact results under Euclidean distance, and want to choose channels per query. Raw and z-normalised subsequences both work.</p>

<p>Think twice if:</p>

<ul>
  <li><strong>Your query length changes.</strong> MS-Index is fixed-length: the query length is a build parameter. For variable lengths, see MULISSE.</li>
  <li><strong>You run only a handful of queries.</strong> Index construction costs about as much as ST-index (both spend the time on DFTs). On Stocks, MS-Index only beats plain MASS on total cost after about 45 queries.</li>
  <li><strong>Memory is tight.</strong> The index summarises every subsequence. On Stocks with 2,000 series (430 MB), the raw index was 1,923 MB, about 4.5x the data; normalised 5.2x. MULISSE, at 5%, is far smaller and pays for it in query time.</li>
  <li><strong>Your queries are far from the data.</strong> For noisy or out-of-distribution queries, the contrast between near and far windows shrinks, pruning collapses, and MS-Index degrades to roughly MASS plus tree overhead. Use a sequential scan there. A hybrid that picks by estimated query difficulty is future work.</li>
  <li><strong>You want DTW.</strong> Euclidean only.</li>
</ul>

<h2 id="running-it">Running it</h2>

<p>The repository is Java with Maven. There is no library API; everything is driven from <code class="language-plaintext highlighter-rouge">run.sh</code>. Build the jar first (the script expects <code class="language-plaintext highlighter-rouge">target/MS-Index-1.0-jar-with-dependencies.jar</code>):</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/JdHondt/MS-Index.git
<span class="nb">cd </span>MS-Index
mvn clean package
</code></pre></div></div>

<p>Then edit the variables at the top of <code class="language-plaintext highlighter-rouge">run.sh</code> and run it:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">algorithmType</span><span class="o">=</span>MSINDEX     <span class="c"># or BRUTE_FORCE, MASS, ST_INDEX, DSTREE, KV_MATCH</span>
<span class="nv">dataPath</span><span class="o">=</span>data/synthetic   <span class="c"># see data/instructions.md for the paper's datasets</span>
<span class="nv">N</span><span class="o">=</span>100                     <span class="c"># number of time series to load</span>
<span class="nv">channels</span><span class="o">=</span><span class="nt">-1</span>               <span class="c"># channels per series, -1 = all</span>
<span class="nv">nQueryChannels</span><span class="o">=</span><span class="nt">-1</span>         <span class="c"># channels used in the query, -1 = all</span>
<span class="nv">qLen</span><span class="o">=</span>730                  <span class="c"># query (and index) subsequence length</span>
<span class="nv">K</span><span class="o">=</span>1                       <span class="c"># neighbours to return</span>
<span class="nv">normalize</span><span class="o">=</span><span class="nb">false</span>           <span class="c"># z-normalised subsequences</span>
<span class="nv">nQueries</span><span class="o">=</span>100
<span class="nv">runtimeMode</span><span class="o">=</span>FULL_NO_STORE <span class="c"># FULL, INDEX, QUERY variants</span>

./run.sh
</code></pre></div></div>

<h2 id="links">Links</h2>

<ul>
  <li>Paper page on this site: <a href="/publication/msindex_2026">MS-Index</a></li>
  <li>The earlier workshop paper on variable-length search: <a href="/publication/multisa25">MULISSE</a></li>
  <li>arXiv: <a href="https://arxiv.org/abs/2512.14723">2512.14723</a></li>
  <li>Code: <a href="https://github.com/JdHondt/MS-Index">github.com/JdHondt/MS-Index</a> (MIT licence)</li>
</ul>

<h2 id="cite-this">Cite this</h2>

<div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">dhondt2025msindex</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">{d'Hondt, Jens and Kortekaas, Teun and Papapetrou, Odysseas and Palpanas, Themis}</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">{{MS-Index}: Fast Top-k Subsequence Search for Multivariate Time Series under {Euclidean} Distance}</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">{Proceedings of the VLDB Endowment}</span><span class="p">,</span>
  <span class="na">volume</span>  <span class="p">=</span> <span class="s">{19}</span><span class="p">,</span>
  <span class="na">number</span>  <span class="p">=</span> <span class="s">{2}</span><span class="p">,</span>
  <span class="na">pages</span>   <span class="p">=</span> <span class="s">{99--112}</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">{2025}</span><span class="p">,</span>
  <span class="na">doi</span>     <span class="p">=</span> <span class="s">{10.14778/3773749.3773751}</span>
<span class="p">}</span>
</code></pre></div></div>]]></content><author><name>Jens E. d&apos;Hondt, PhD</name><email>jens.dhondt@bsc.es</email></author><category term="time series" /><category term="similarity search" /><category term="indexing" /><summary type="html"><![CDATA[How MS-Index finds top-k similar subsequences in multivariate time series when the relevant channels are only chosen at query time, exactly and fast.]]></summary></entry><entry><title type="html">Which distance measure should you use for multivariate time series?</title><link href="https://jensdhondt.com/blog/distance-measures-multivariate-time-series/" rel="alternate" type="text/html" title="Which distance measure should you use for multivariate time series?" /><published>2026-09-14T00:00:00+00:00</published><updated>2026-09-14T00:00:00+00:00</updated><id>https://jensdhondt.com/blog/distance-measures-multivariate-time-series</id><content type="html" xml:base="https://jensdhondt.com/blog/distance-measures-multivariate-time-series/"><![CDATA[<p><strong>TL;DR</strong> If you need a distance measure for multivariate time series and have no time to experiment, start with the channel-dependent Shape-based Distance (SBD-D): in our SIGMOD 2025 study it gave the best accuracy for its runtime, and it has no parameters to tune. If speed is everything, use Lorentzian distance instead of Euclidean; if accuracy is everything and you can afford days of compute, use a tuned channel-independent elastic measure like MSM-I. And do not assume z-score normalization helps: on the 30 datasets we tested, not normalizing at all ranked first.</p>

<h2 id="why-this-is-a-harder-question-than-it-looks">Why this is a harder question than it looks</h2>

<p>For a univariate time series, a distance measure only has to decide how to deal with time. Two recordings of the same event can be shifted, stretched, or noisy, and the measure either corrects for those distortions or it does not. Decades of work have gone into this, and we have a good idea of what works.</p>

<figure>
  <a href="/images/blog/distance-measures/intro-example.png" target="_blank" rel="noopener"><img src="/images/blog/distance-measures/intro-example.png" alt="A query series Q is compared with reference A, labelled standing, and reference B, labelled walking. Dotted lines show how Shape-based distance aligns Q with each reference: Q matches A after a global shift (distance 0.4), while the distinct patterns of B do not line up with Q (distance 0.7). A note says Euclidean distance fails to identify Q as standing because it cannot align the distinct patterns." style="width:100%" /></a>
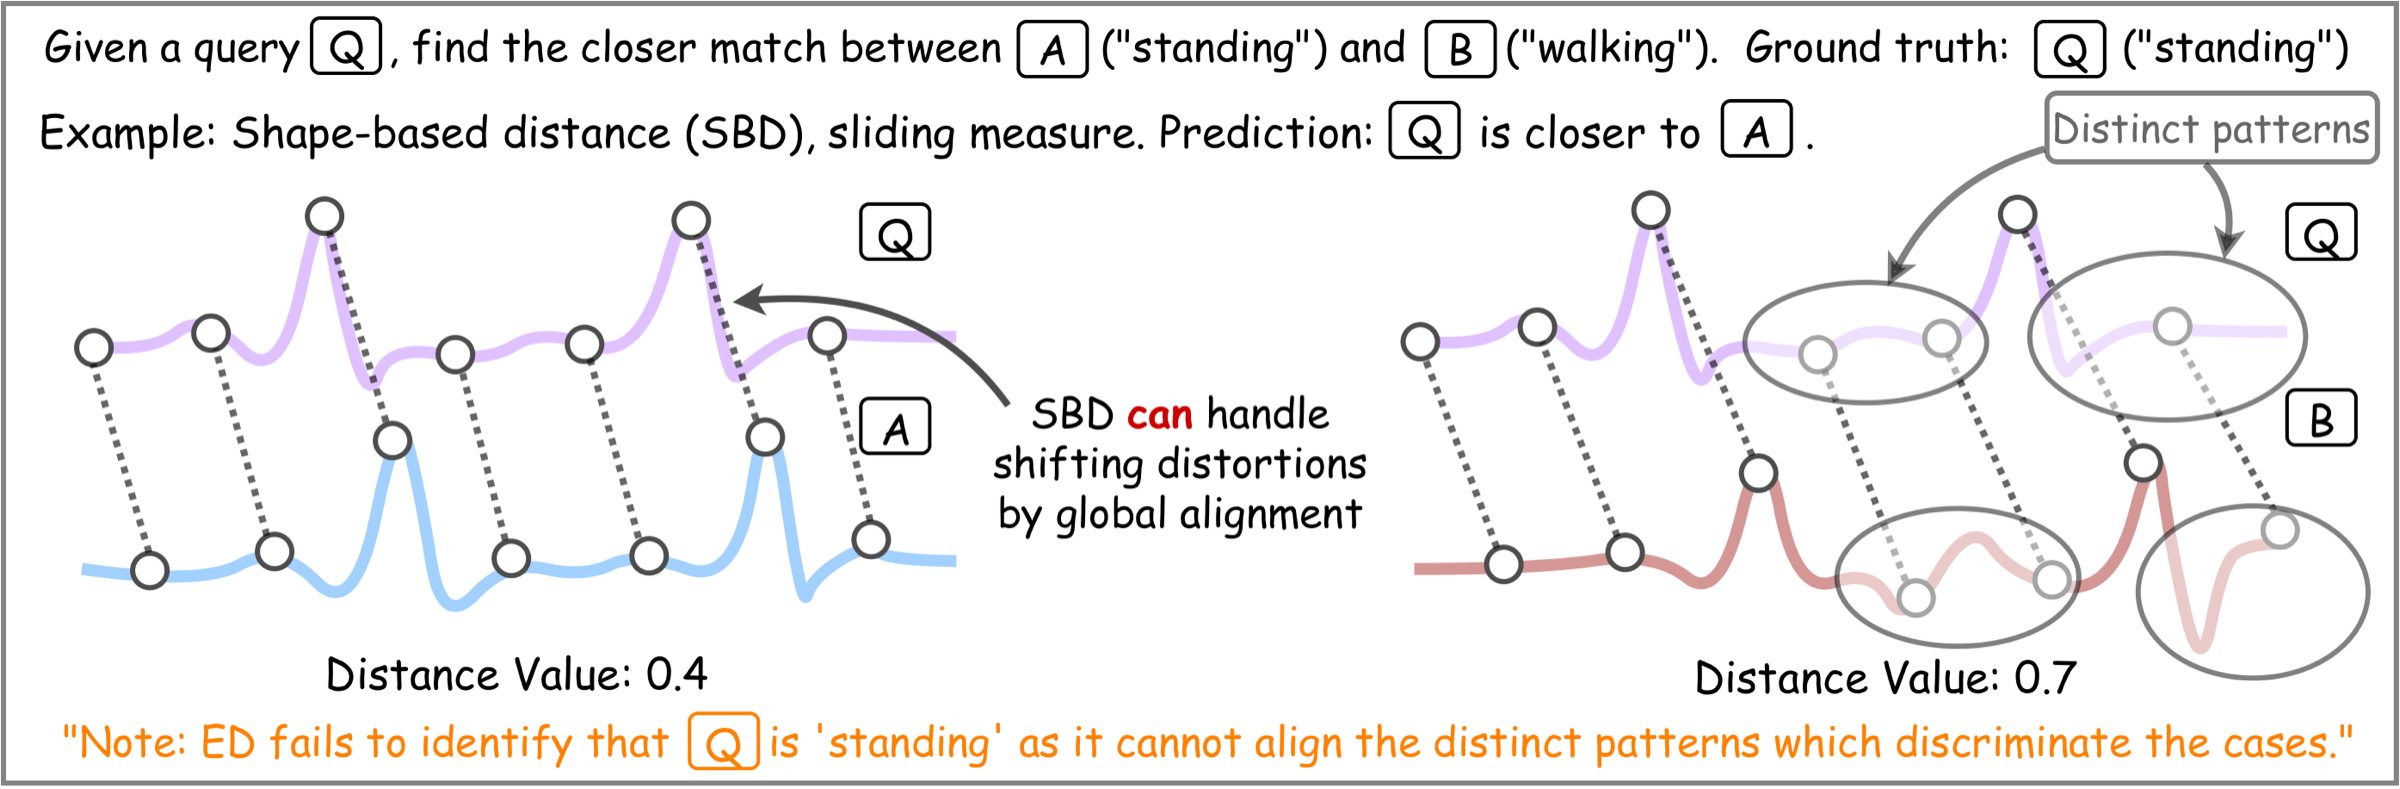
  <figcaption>Why the choice of measure matters. The query is a shifted version of a "standing" recording. Shape-based distance (SBD) corrects the shift with one global alignment and picks the right neighbour; Euclidean distance (ED) compares time point <em>i</em> with time point <em>i</em>, misses the alignment, and picks the wrong one. (Synthetic data inspired by the UEA StandWalkJump dataset; Figure 1 of the paper. Click to enlarge.)</figcaption>
</figure>

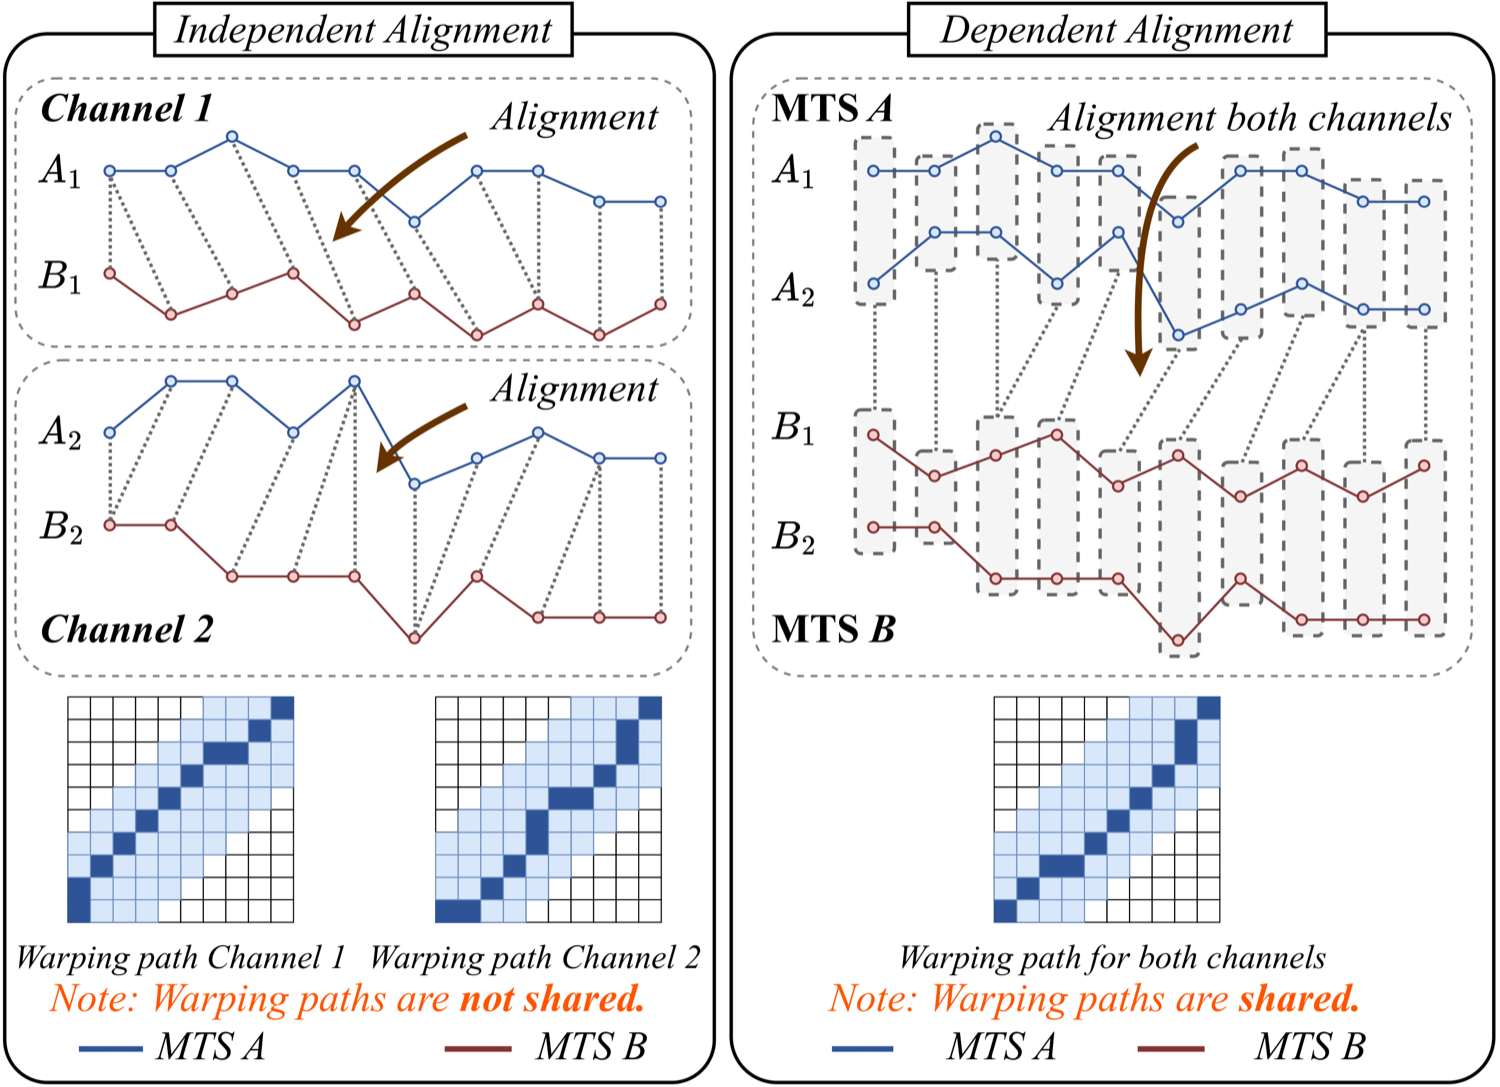
<p>Multivariate time series add a second question: how do you deal with the channels? You can treat every channel as its own univariate series, compute a distance per channel, and add them up. We call that the <strong>channel-independent</strong> model. Or you can treat the whole matrix as one object, so that a shift or a warping is shared by all channels. That is the <strong>channel-dependent</strong> model. For DTW these are the well-known DTW-I and DTW-D variants, and the same split exists for almost every other measure, and for normalization too: do you z-score each channel on its own, or with statistics over the whole series?</p>

<figure>
  <a href="/images/blog/distance-measures/dependent-independent.png" target="_blank" rel="noopener"><img src="/images/blog/distance-measures/dependent-independent.png" alt="Left, independent alignment: channel 1 and channel 2 of two series A and B are each aligned separately with DTW, giving two different warping paths. Right, dependent alignment: both channels are aligned together, giving one warping path shared by both channels." style="width:85%" /></a>
  <figcaption>Channel-independent (left) versus channel-dependent (right) DTW. With DTW-I every channel gets its own warping path; with DTW-D a single warping path is shared by all channels. (Figure 3 of the paper.)</figcaption>
</figure>

<p>Almost all earlier work on multivariate distances only ever tried per-channel z-score, and only compared lock-step and elastic measures. That left a lot of the design space untested, which is what motivated the study.</p>

<h2 id="the-families-of-measures-in-plain-words">The families of measures, in plain words</h2>

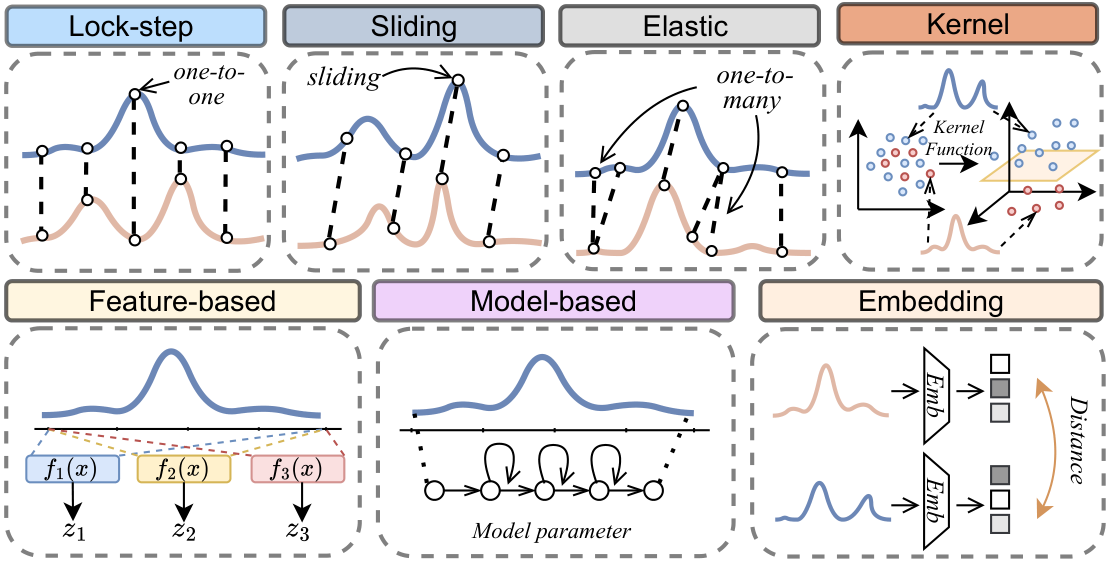
<p>The survey we wrote with John Paparrizos’ group groups more than 100 measures into seven categories. The SIGMOD study uses the same categories, plus ensembles as an eighth.</p>

<figure>
  <img src="/images/blog/distance-measures/temporal-models.png" alt="Seven small diagrams. Lock-step: one-to-one links between time points. Sliding: links shifted by one global offset. Elastic: one-to-many links. Kernel: series mapped into a higher-dimensional space by a kernel function. Feature-based: features f1, f2, f3 computed from a series. Model-based: a state-transition model fitted to a series. Embedding: two series passed through an embedding network and compared in the embedding space." style="width:85%" />
  <figcaption>The seven temporal models, one per category of measure. (Figure 2 of the paper, by Fan Yang.)</figcaption>
</figure>

<ul>
  <li><strong>Lock-step measures</strong> compare value <em>i</em> of one series with value <em>i</em> of the other and add up the differences. Euclidean is the obvious example; Lorentzian and L1 are others. Fast, but blind to misalignment in time.</li>
  <li><strong>Sliding measures</strong> try every global shift between the two series and keep the best one. SBD, the distance behind k-Shape clustering, is the standard example.</li>
  <li><strong>Elastic measures</strong> allow one-to-many mappings between time points, so they absorb local stretching and compression. DTW is the famous one; newer members include MSM, TWE, ERP, and LCSS.</li>
  <li><strong>Kernel measures</strong> implicitly map series to a higher-dimensional space through a kernel function, such as GAK or SINK.</li>
  <li><strong>Feature-based measures</strong> replace a series with a vector of statistics (mean, entropy, slope, and so on) and compare those. Catch22 and TSFresh are the common feature sets.</li>
  <li><strong>Model-based measures</strong> fit a probabilistic model, such as a Gaussian or an HMM, to each series and compare the models, for example with KL divergence.</li>
  <li><strong>Embedding measures</strong> learn a new representation and compute a distance there. Deep learning methods like TS2Vec live here, alongside GRAIL and PCA-based measures.</li>
</ul>

<h2 id="what-the-study-did">What the study did</h2>

<p>We evaluated 30 standalone measures across these 8 categories, each in channel-independent and channel-dependent form where that makes sense (46 variants in total), combined with 13 normalization methods plus the option of not normalizing. Accuracy was measured with a 1-NN classifier on all 30 datasets of the UEA archive, both with supervised parameter tuning (leave-one-out cross-validation) and with a single default setting, and the main comparisons were repeated on clustering (UEA) and anomaly detection (the TSB-AD-M archive, 200 series). Differences were checked with Wilcoxon and Friedman-Nemenyi tests rather than eyeballed. The code is on GitHub as <a href="https://github.com/TheDatumOrg/MTSDistEval">MTSDistEval</a>.</p>

<h2 id="a-practical-decision-guide">A practical decision guide</h2>

<p>The table below is my reading of Table 11 and Section 6 of the paper.</p>

<table>
  <thead>
    <tr>
      <th>If your situation is…</th>
      <th>Start with</th>
      <th>Why</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Classification, clustering, or pattern matching, and you have no time to experiment</td>
      <td><strong>SBD-D</strong> (channel-dependent sliding)</td>
      <td>Best accuracy-to-runtime trade-off; no parameters</td>
    </tr>
    <tr>
      <td>Runtime is the hard constraint (sub-millisecond per comparison)</td>
      <td><strong>Lorentzian</strong> (lock-step)</td>
      <td>Significantly more accurate than Euclidean at the same cost</td>
    </tr>
    <tr>
      <td>Accuracy is all that matters and you have labeled data plus days of compute</td>
      <td><strong>MSM-I with tuned parameters</strong> (channel-independent elastic)</td>
      <td>Only tuned MSM-I and TWE-I beat SBD-D significantly</td>
    </tr>
    <tr>
      <td>You already picked an elastic measure and wonder about I versus D</td>
      <td><strong>Channel-independent</strong></td>
      <td>Independent alignment wins significantly for elastic measures</td>
    </tr>
    <tr>
      <td>You picked anything other than an elastic measure</td>
      <td><strong>Channel-dependent</strong></td>
      <td>Dependent variants win significantly for sliding and kernel measures</td>
    </tr>
    <tr>
      <td>Anomaly detection, where the distortion <em>is</em> the signal</td>
      <td><strong>Euclidean</strong> (lock-step)</td>
      <td>Beat every sliding and elastic measure we tested</td>
    </tr>
  </tbody>
</table>

<p>The main findings behind that table:</p>

<ul>
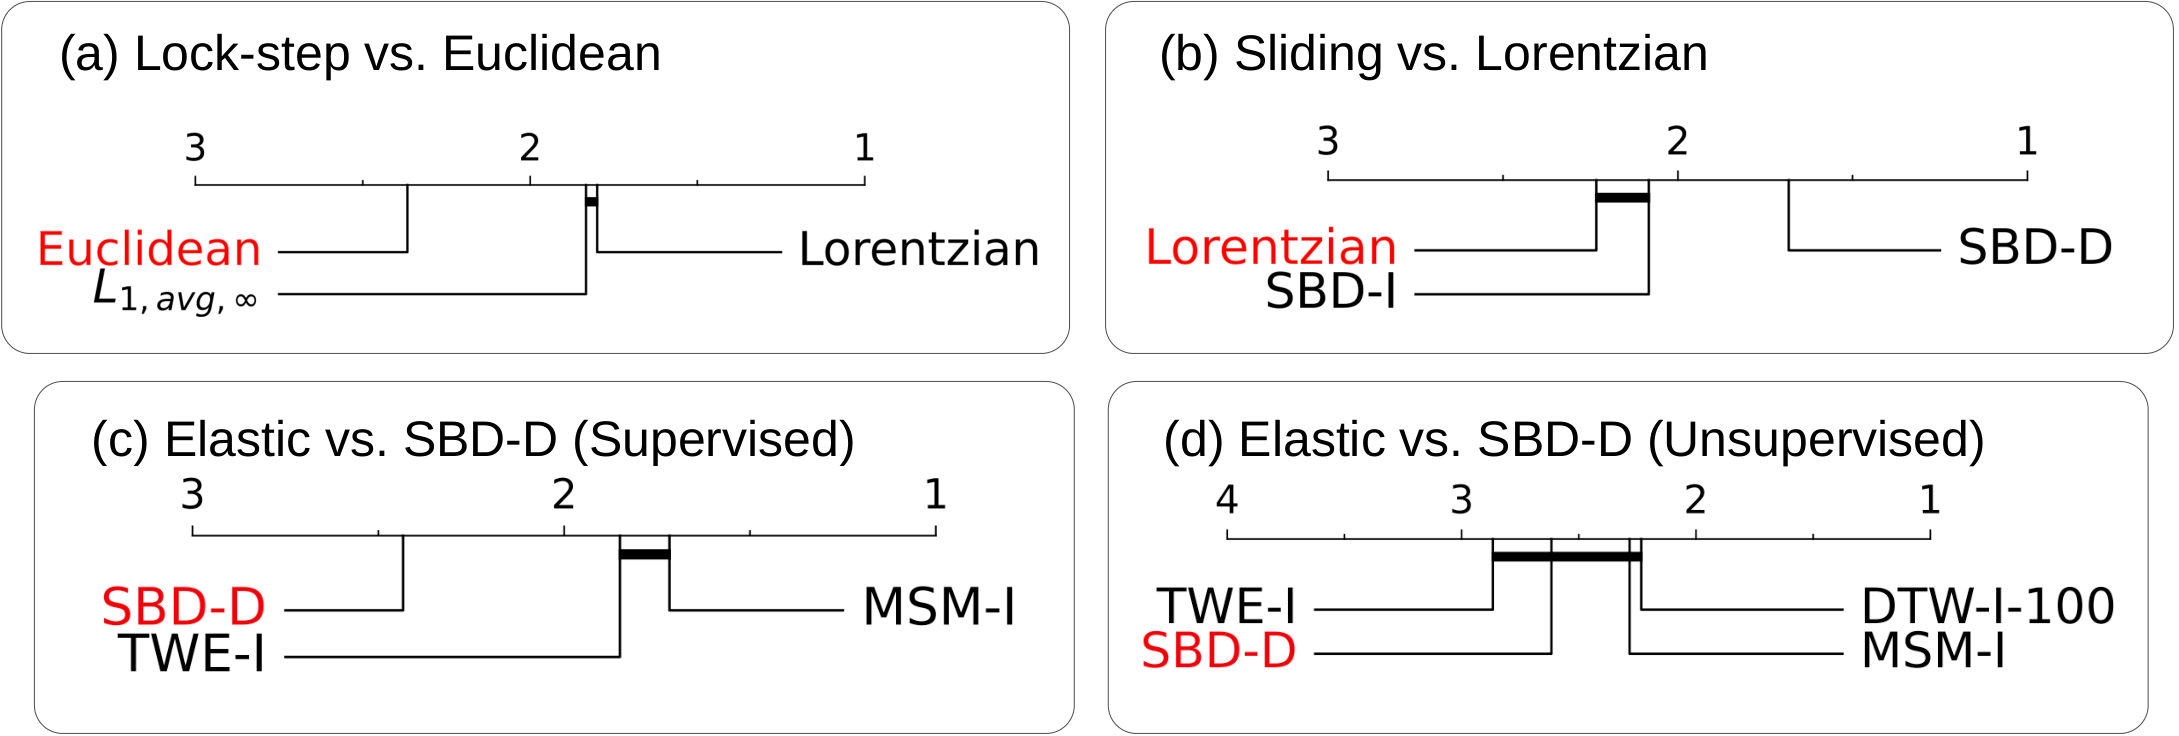
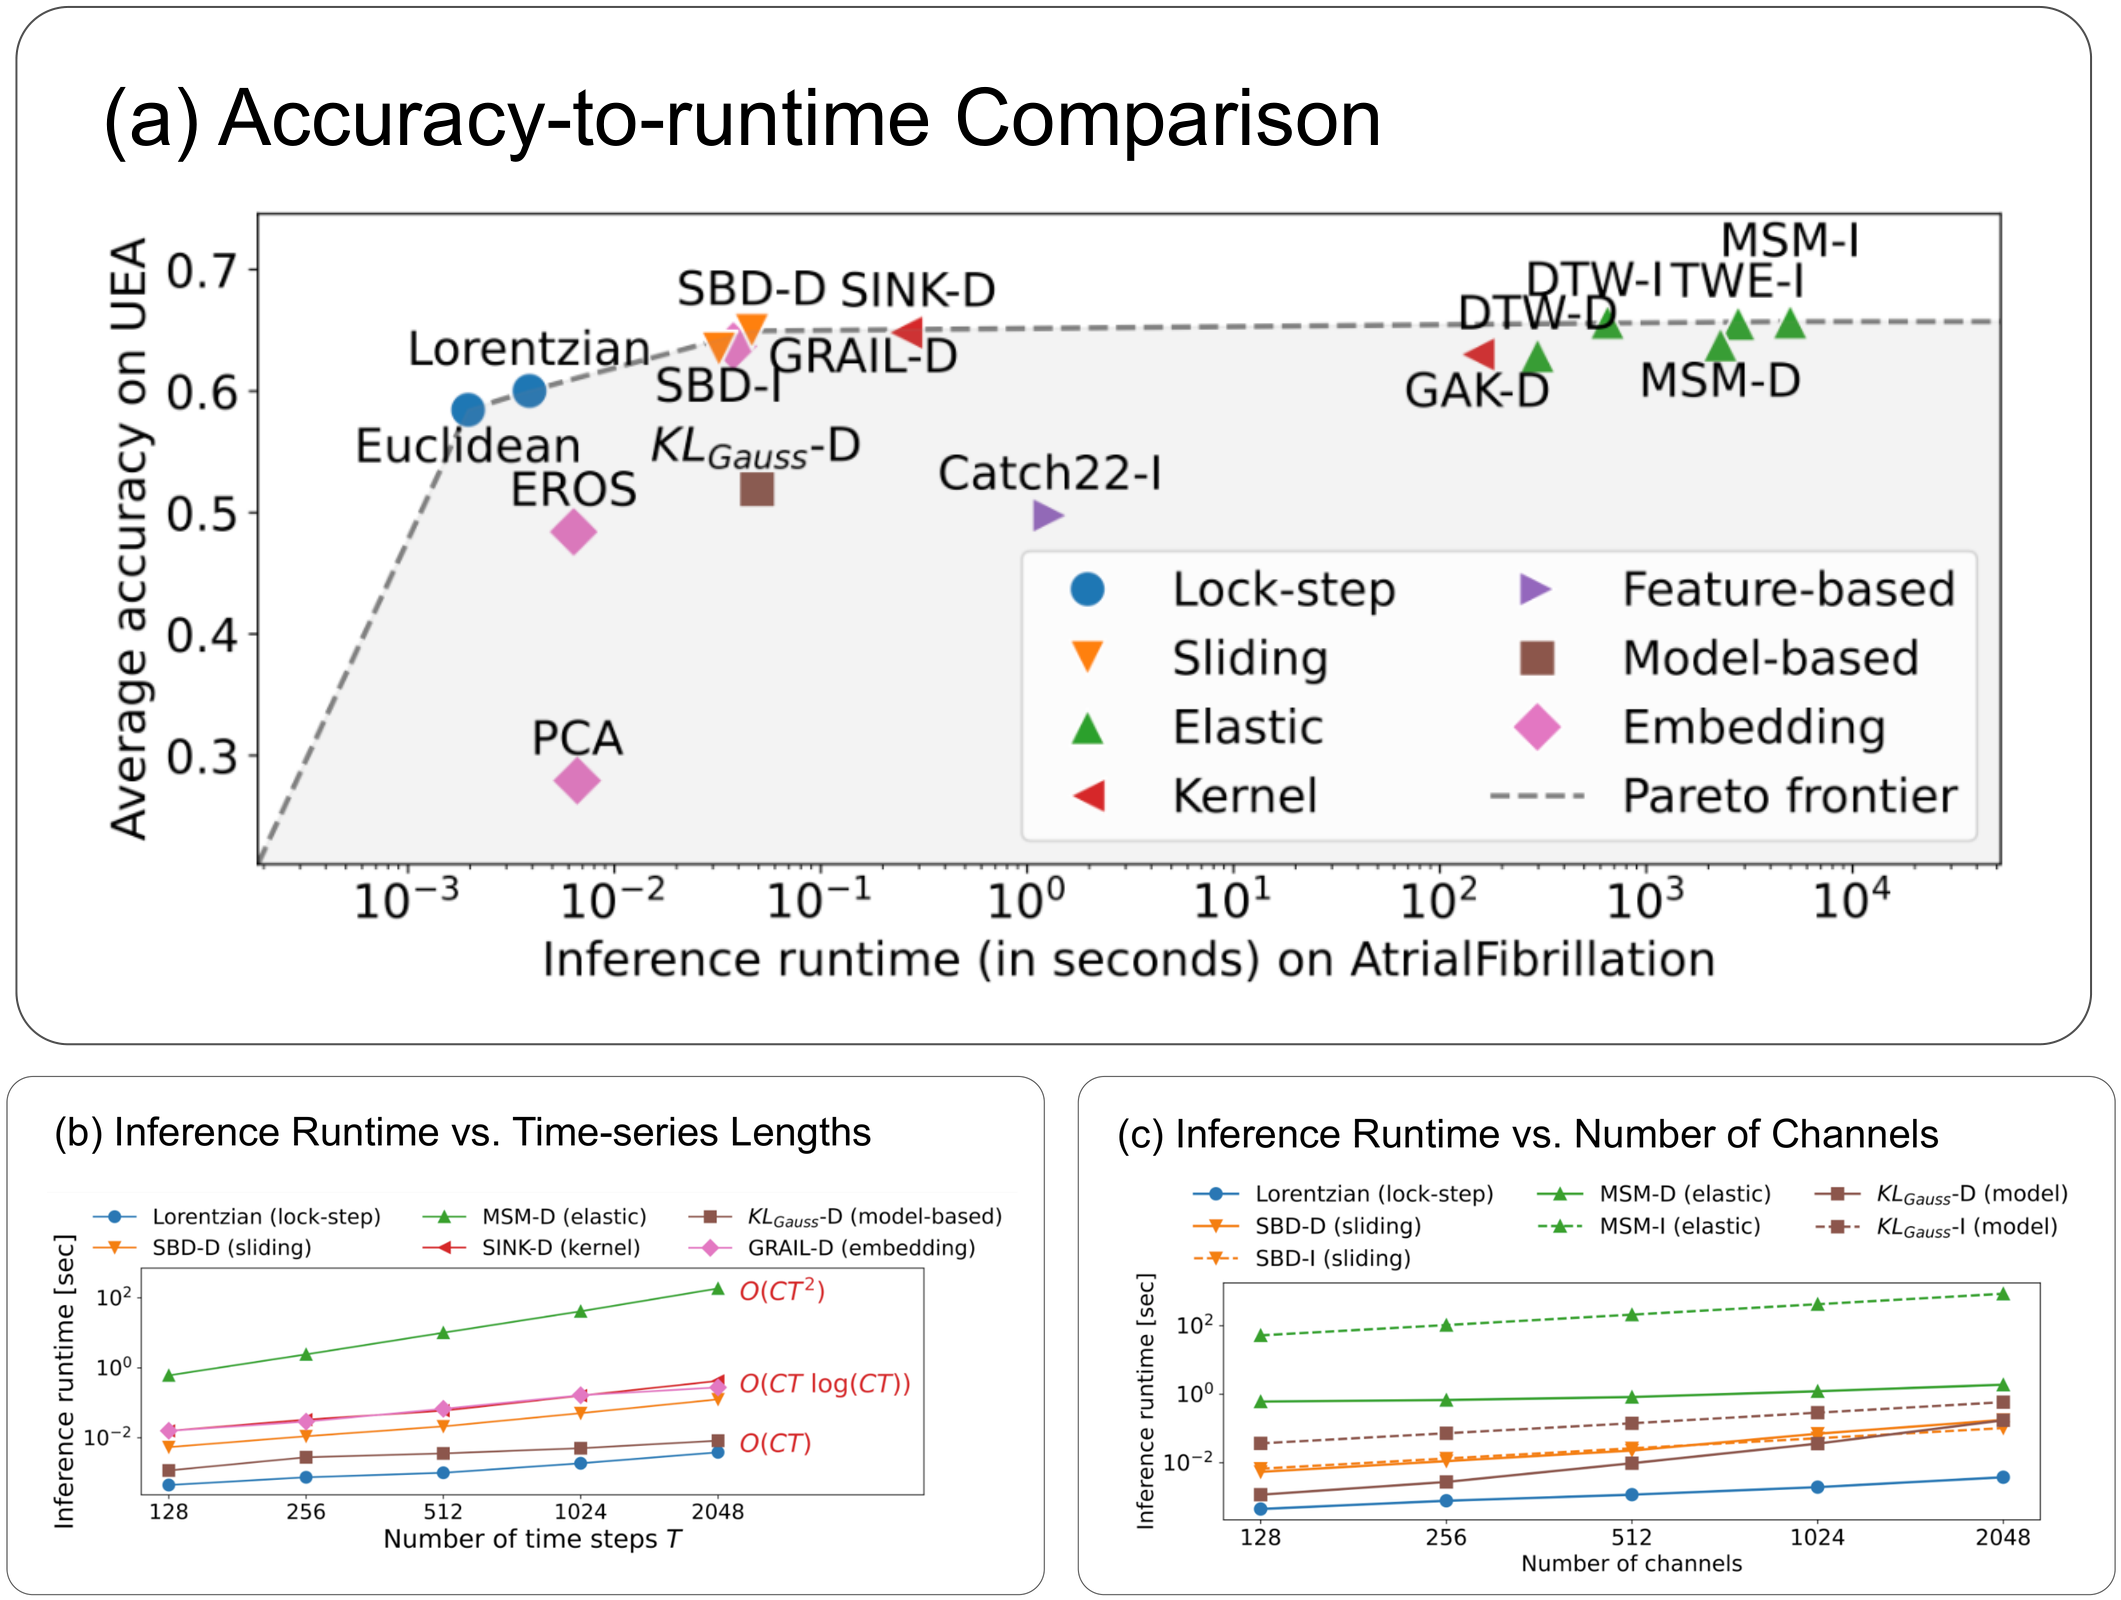
  <li><strong>Sliding measures are the sweet spot.</strong> SBD-D significantly outperformed the best lock-step measure on classification (average accuracy 0.68 versus 0.63 for Lorentzian) and on clustering (Rand index 0.75 versus 0.66 for Euclidean). On runtime, SBD-D took about 0.05 seconds on the AtrialFibrillation dataset, against 4982 seconds for MSM-I and 297 seconds for DTW-D: four to five orders of magnitude for roughly one percentage point of accuracy (0.65 versus about 0.66). SBD-D is O(CT log CT); elastic measures are O(CT^2).</li>
  <li><strong>Newer elastic measures beat DTW, but only when tuned.</strong> With leave-one-out tuning, MSM-I and TWE-I were the only measures in the whole study that significantly beat SBD-D. With fixed default parameters, no elastic measure did, and DTW-I never did in either setting.</li>
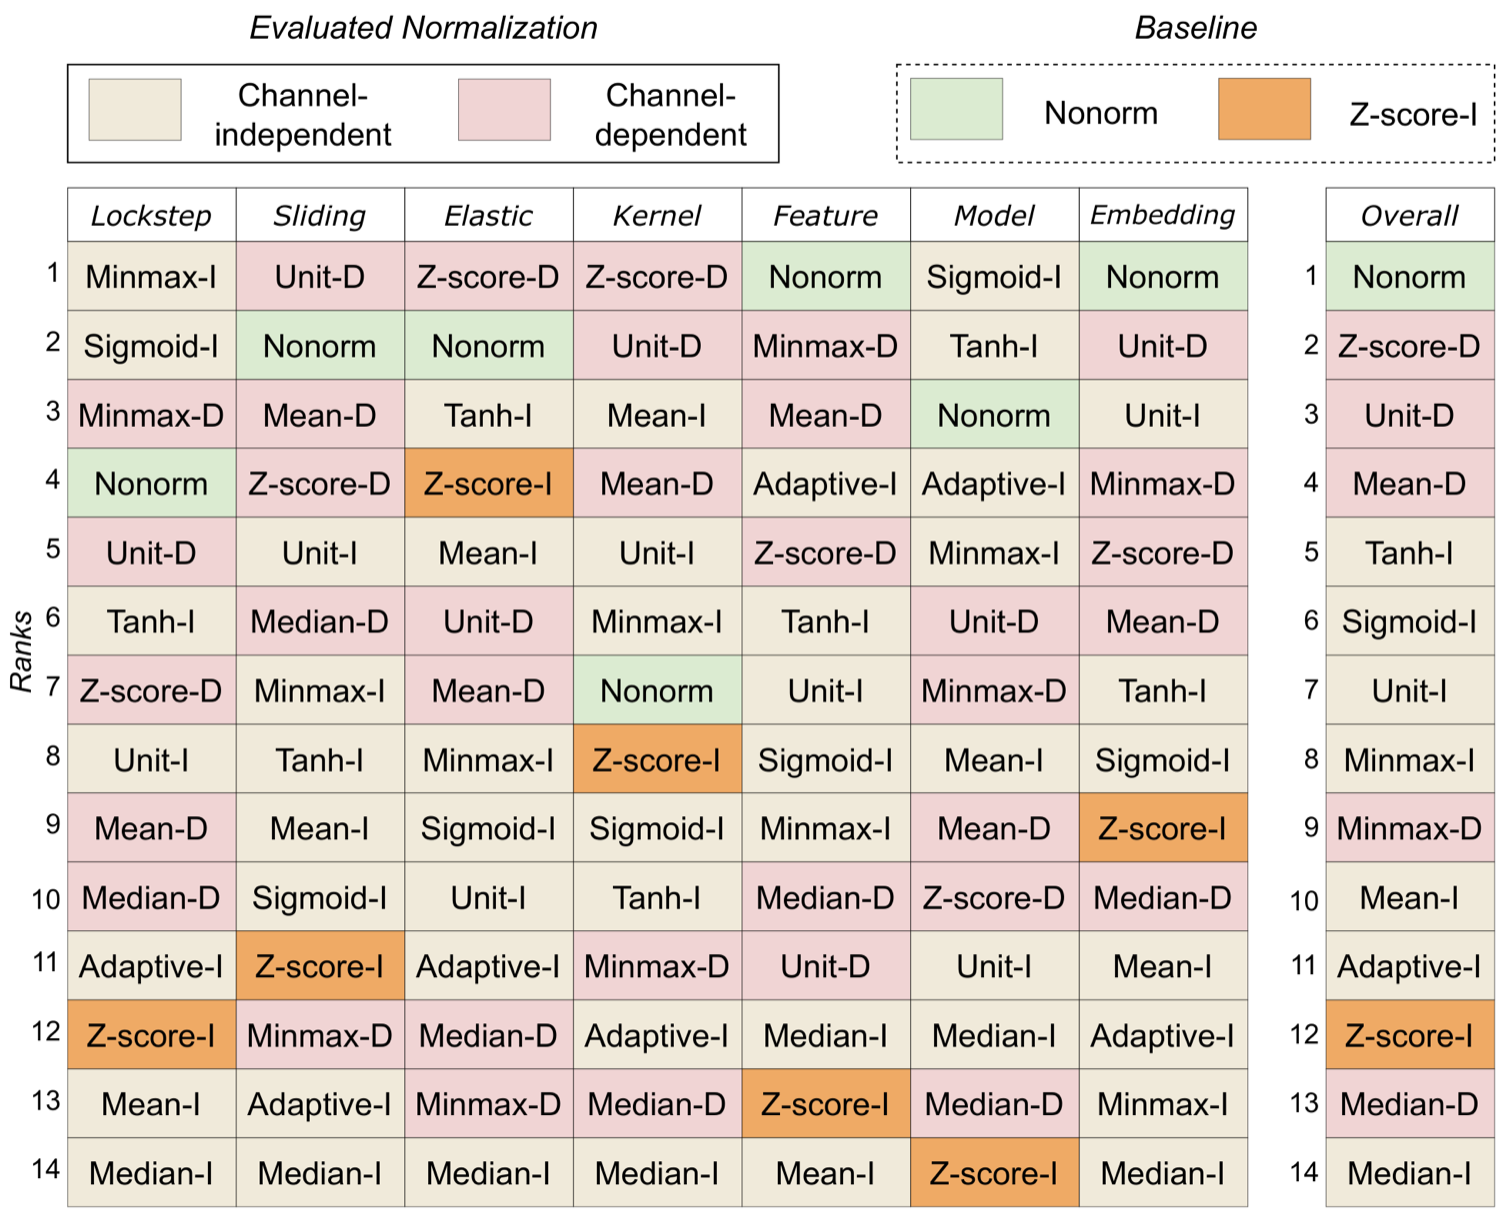
  <li><strong>Z-score is not automatically the right normalization.</strong> Per-channel z-score, the default in almost all multivariate work, ranked 12th out of 14 options in the overall meta-ranking. Not normalizing ranked first and was in the top four for every family except kernel measures. The Friedman-Nemenyi test found no normalization significantly better than the rest, which suggests the current methods, all direct extensions of univariate ones, are simply not designed for multivariate data.</li>
  <li><strong>Independent channel treatment only helps elastic measures.</strong> Pooled over all measures, the two channel models tie. Per family: dependent wins significantly for sliding and kernel measures, independent wins significantly for elastic measures. Our explanation is that global shifts (what sliding measures fix) tend to hit all sensors at once, whereas local jitter (what elastic measures fix) tends to hit one channel at a time.</li>
  <li><strong>Euclidean is not your best lock-step choice, except for anomaly detection.</strong> Lorentzian, L1, and L1,avg,inf all significantly beat Euclidean on classification. For anomaly detection with a 1-NN detector the ranking flipped: Euclidean significantly beat Lorentzian, SBD-D, DTW-D, DTW-I, and SBD-I. When you are looking for distortions, you do not want a measure that corrects them away.</li>
  <li><strong>Deep-learning embeddings did not win.</strong> TS2Vec and GRAIL beat Euclidean, but none of the embedding, feature-based, model-based, or kernel measures matched SBD-D.</li>
</ul>

<figure>
  <a href="/images/blog/distance-measures/cd-lockstep-sliding-elastic.png" target="_blank" rel="noopener"><img src="/images/blog/distance-measures/cd-lockstep-sliding-elastic.png" alt="Four critical difference diagrams. (a) Lock-step versus Euclidean: Lorentzian ranks best, Euclidean worst. (b) Sliding versus Lorentzian: SBD-D ranks best. (c) Elastic versus SBD-D with supervised tuning: MSM-I ranks best, ahead of TWE-I and SBD-D. (d) Elastic versus SBD-D with unsupervised tuning: DTW-I-100, MSM-I, SBD-D and TWE-I are close together." style="width:100%" /></a>
  <figcaption>The step-by-step comparison behind the decision guide, on 1-NN classification across the UEA archive without normalization. Each panel ranks measures by their average rank over the datasets (1 is best, on the right); the red measure is the baseline for that panel, and measures joined by a thick horizontal bar are not significantly different. (Figure 5 of the paper; click to enlarge.)</figcaption>
</figure>

<figure>
  <a href="/images/blog/distance-measures/normalization-ranking.png" target="_blank" rel="noopener"><img src="/images/blog/distance-measures/normalization-ranking.png" alt="A table ranking 14 normalization options from 1 to 14 for each family of measures (lock-step, sliding, elastic, kernel, feature, model, embedding) and overall. Cells are coloured by channel-independent, channel-dependent, no normalization (green) or per-channel z-score (orange). Overall, no normalization ranks 1st and per-channel z-score (Z-score-I) ranks 12th." style="width:80%" /></a>
  <figcaption>Meta-ranking of the normalization options per family and overall. Green is no normalization, orange is the usual per-channel z-score (Z-score-I); the suffixes -I and -D mean normalizing each channel on its own or with statistics over all channels. (Figure 4a of the paper.)</figcaption>
</figure>

<h2 id="dtw-versus-euclidean-in-one-paragraph">DTW versus Euclidean, in one paragraph</h2>

<p>Because this is the comparison people actually search for: on multivariate classification, DTW-I and DTW-D scored higher than Euclidean on average, but DTW never significantly beat the parameter-free SBD-D, and it costs hours to days of compute on the larger UEA datasets. About to reach for DTW by default? Try SBD-D first. About to reach for Euclidean? Try Lorentzian.</p>

<figure>
  <a href="/images/blog/distance-measures/runtime.png" target="_blank" rel="noopener"><img src="/images/blog/distance-measures/runtime.png" alt="Three plots. (a) Average accuracy on UEA against inference runtime on AtrialFibrillation on a log scale, with a Pareto frontier: Euclidean and Lorentzian are fastest, SBD-D reaches near-top accuracy at about 0.05 seconds, and the elastic measures MSM-I, TWE-I and DTW reach similar accuracy at hundreds to thousands of seconds. (b) Runtime against series length: lock-step grows as O(CT), sliding and kernel as O(CT log CT), elastic as O(CT squared). (c) Runtime against number of channels for the top measure of each category." style="width:100%" /></a>
  <figcaption>Accuracy against runtime. (a) Average UEA accuracy versus inference time on AtrialFibrillation: SBD-D sits at the knee of the Pareto frontier, while elastic measures buy a little more accuracy for four to five orders of magnitude more time. (b, c) How runtime grows with series length and number of channels. (Figure 9 of the paper; click to enlarge.)</figcaption>
</figure>

<h2 id="code-one-lock-step-and-one-elastic-distance-in-python">Code: one lock-step and one elastic distance in Python</h2>

<p>I used <a href="https://www.aeon-toolkit.org/">aeon</a> 1.1.0 here because it ships multivariate versions of Euclidean, DTW, MSM, and SBD out of the box. Series are arrays of shape <code class="language-plaintext highlighter-rouge">(n_channels, n_timepoints)</code>.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">numpy</span> <span class="k">as</span> <span class="n">np</span>
<span class="kn">from</span> <span class="nn">aeon.distances</span> <span class="kn">import</span> <span class="n">euclidean_distance</span><span class="p">,</span> <span class="n">msm_distance</span><span class="p">,</span> <span class="n">sbd_distance</span>

<span class="n">rng</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="n">random</span><span class="p">.</span><span class="n">default_rng</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>
<span class="n">x</span> <span class="o">=</span> <span class="n">rng</span><span class="p">.</span><span class="n">normal</span><span class="p">(</span><span class="n">size</span><span class="o">=</span><span class="p">(</span><span class="mi">3</span><span class="p">,</span> <span class="mi">100</span><span class="p">))</span>  <span class="c1"># 3 channels, 100 time points
</span><span class="n">y</span> <span class="o">=</span> <span class="n">rng</span><span class="p">.</span><span class="n">normal</span><span class="p">(</span><span class="n">size</span><span class="o">=</span><span class="p">(</span><span class="mi">3</span><span class="p">,</span> <span class="mi">100</span><span class="p">))</span>

<span class="c1"># Lock-step: Euclidean over all channels and time points.
# Channel-independent and channel-dependent variants are identical here.
</span><span class="n">d_lock</span> <span class="o">=</span> <span class="n">euclidean_distance</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">)</span>

<span class="c1"># Elastic: Move-Split-Merge. independent=True gives MSM-I, the variant
# the study recommends when accuracy matters. c is the split/merge cost;
# c=0.5 was the default that worked best across the UEA archive.
</span><span class="n">d_msm_i</span> <span class="o">=</span> <span class="n">msm_distance</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">c</span><span class="o">=</span><span class="mf">0.5</span><span class="p">,</span> <span class="n">independent</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
<span class="n">d_msm_d</span> <span class="o">=</span> <span class="n">msm_distance</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">c</span><span class="o">=</span><span class="mf">0.5</span><span class="p">,</span> <span class="n">independent</span><span class="o">=</span><span class="bp">False</span><span class="p">)</span>

<span class="c1"># Sliding: aeon's multivariate SBD averages per-channel SBD, so this is
# SBD-I. For SBD-D (one shift shared by all channels, computed with a 2D
# FFT) see the MTSDistEval repository linked above.
</span><span class="n">d_sbd_i</span> <span class="o">=</span> <span class="n">sbd_distance</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">standardize</span><span class="o">=</span><span class="bp">False</span><span class="p">)</span>
</code></pre></div></div>

<p>Note the <code class="language-plaintext highlighter-rouge">standardize=False</code>: aeon z-scores each series inside <code class="language-plaintext highlighter-rouge">sbd_distance</code> by default, which is exactly the normalization the study found no benefit from on multivariate data.</p>

<h2 id="where-to-go-next">Where to go next</h2>

<ul>
  <li>The full paper: <a href="/publication/sigmod_2025">A Structured Study of Multivariate Time-Series Distance Measures</a>, SIGMOD 2025, <a href="https://doi.org/10.1145/3725258">doi:10.1145/3725258</a>. The guidelines are in Section 6.</li>
  <li>The earlier, smaller version: <a href="/publication/icde_jens_talk">Beyond the Dimensions</a>, ICDE 2024 MulTiSa workshop. That study compared 12 measures on the UEA archive and found no single winner; the SIGMOD paper is what happened when we added the missing families, normalizations, tasks, and statistics.</li>
  <li>Background reading: <a href="/publication/book_chapter_2024">A Survey on Time-Series Distance Measures</a>, covering the 100+ measures and 7 categories the study draws from.</li>
</ul>

<h2 id="cite-this">Cite this</h2>

<div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">dhondt2025structured</span><span class="p">,</span>
  <span class="na">author</span>    <span class="p">=</span> <span class="s">{d'Hondt, Jens E. and Li, Haojun and Yang, Fan and Papapetrou, Odysseas and Paparrizos, John}</span><span class="p">,</span>
  <span class="na">title</span>     <span class="p">=</span> <span class="s">{A Structured Study of Multivariate Time-Series Distance Measures}</span><span class="p">,</span>
  <span class="na">journal</span>   <span class="p">=</span> <span class="s">{Proceedings of the ACM on Management of Data}</span><span class="p">,</span>
  <span class="na">volume</span>    <span class="p">=</span> <span class="s">{3}</span><span class="p">,</span>
  <span class="na">number</span>    <span class="p">=</span> <span class="s">{3}</span><span class="p">,</span>
  <span class="na">articleno</span> <span class="p">=</span> <span class="s">{121}</span><span class="p">,</span>
  <span class="na">pages</span>     <span class="p">=</span> <span class="s">{1--29}</span><span class="p">,</span>
  <span class="na">year</span>      <span class="p">=</span> <span class="s">{2025}</span><span class="p">,</span>
  <span class="na">month</span>     <span class="p">=</span> <span class="nv">jun</span><span class="p">,</span>
  <span class="na">publisher</span> <span class="p">=</span> <span class="s">{Association for Computing Machinery}</span><span class="p">,</span>
  <span class="na">doi</span>       <span class="p">=</span> <span class="s">{10.1145/3725258}</span>
<span class="p">}</span>
</code></pre></div></div>]]></content><author><name>Jens E. d&apos;Hondt, PhD</name><email>jens.dhondt@bsc.es</email></author><category term="time series" /><category term="distance measures" /><category term="similarity search" /><summary type="html"><![CDATA[A practical guide to picking a distance measure for multivariate time series, based on our SIGMOD 2025 study of 30 measures on 30 datasets.]]></summary></entry></feed>